io.github.chicogong/ffvoice
Offline speech-to-text & speaker diarization MCP server: transcribe audio on-device, no cloud
ffvoice-engine


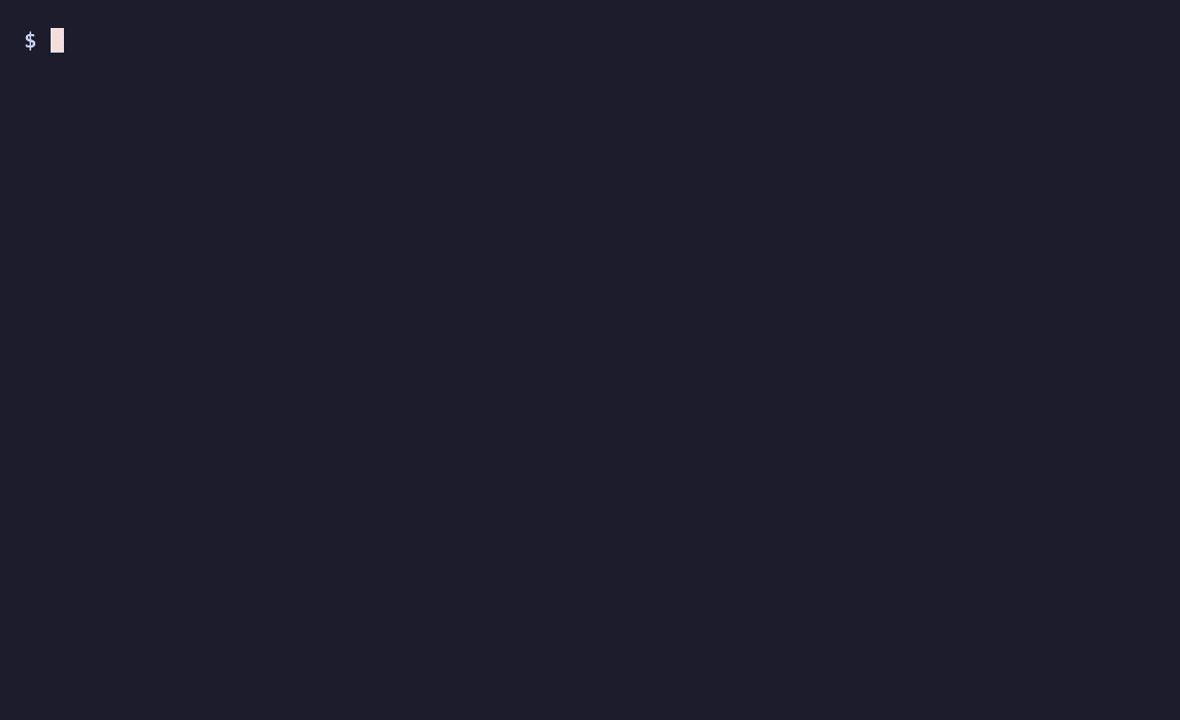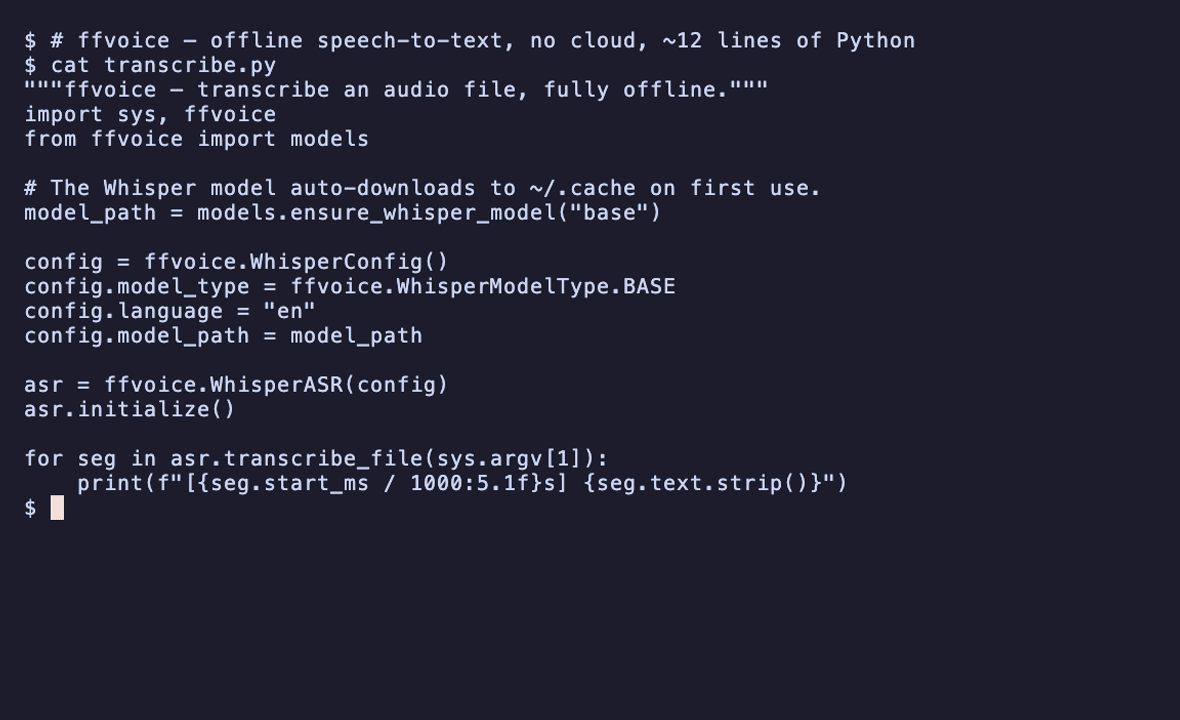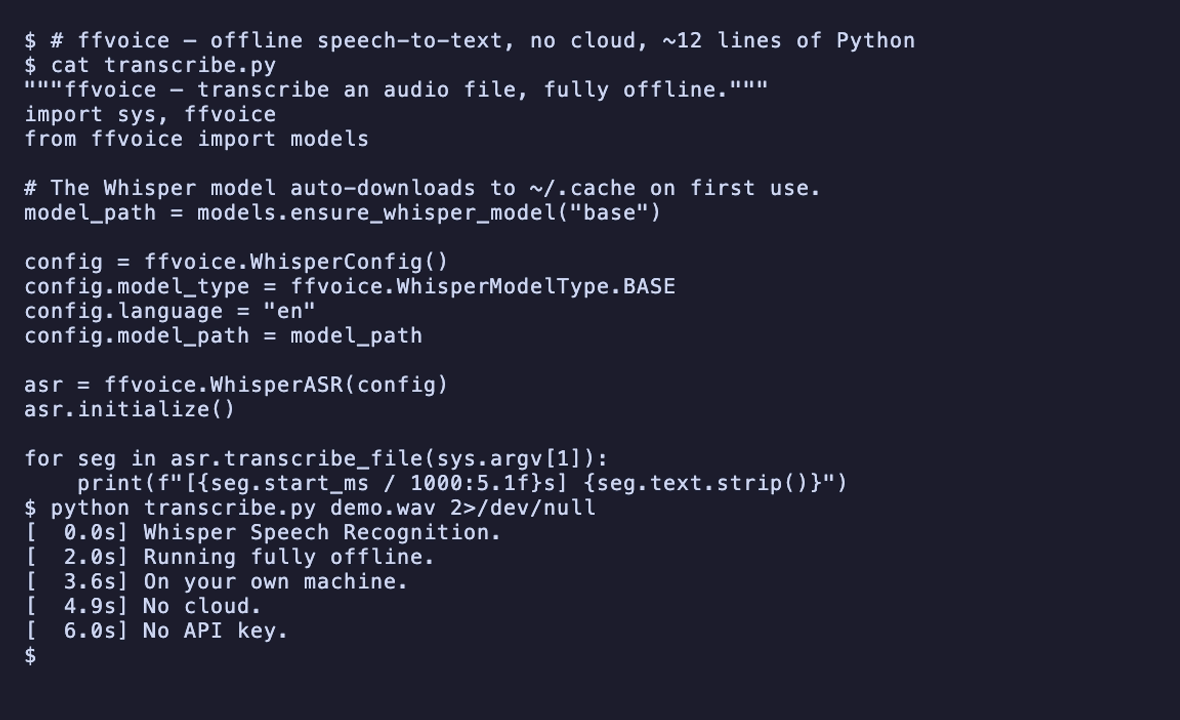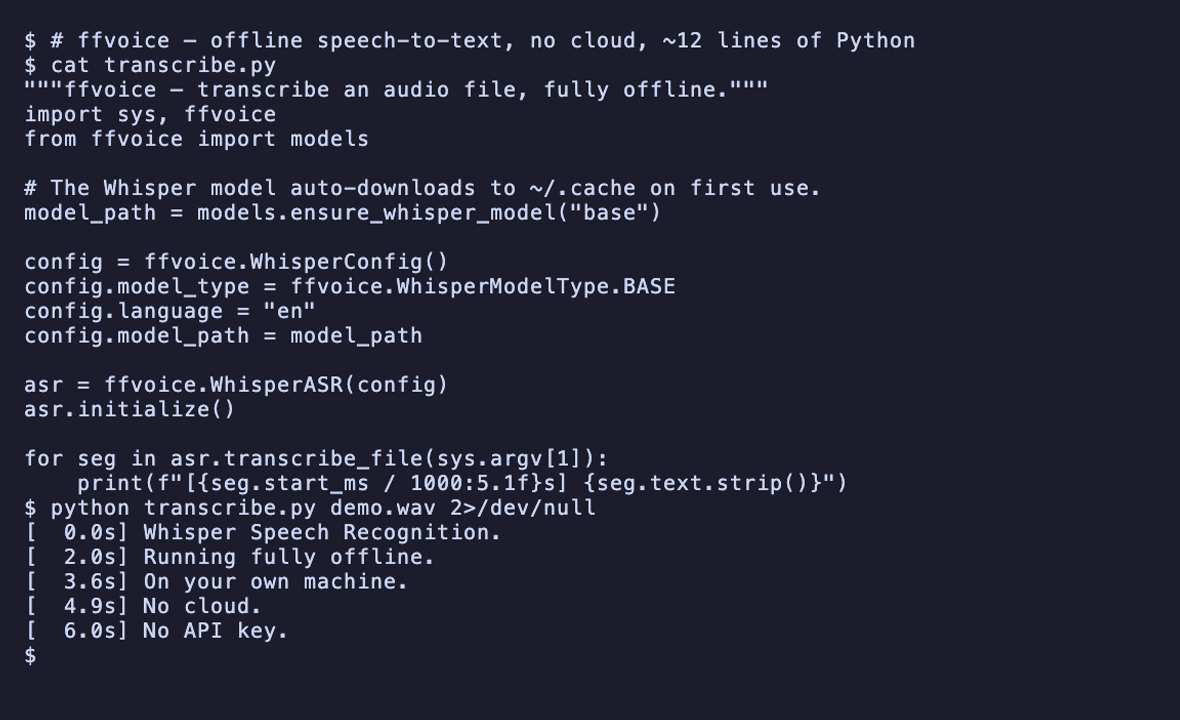
🎙️ Offline speech-to-text & speaker diarization for AI agents — Whisper ASR, live captioning, an MCP server, a CLI and Python bindings. Fully on-device, no cloud API.
🎙️ 离线语音识别 + 说话人分离,AI Agent 开箱即用 —— Whisper 实时转写 · 实时字幕 · MCP server · CLI · Python 绑定 · 100% 本地运行,音频不上云。
Why ffvoice? / 为什么用 ffvoice?
The honest pitch: ffvoice is an integration layer, not a new ASR engine. It embeds whisper.cpp as-is and makes no changes to its accuracy or inference speed. What ffvoice adds is a batteries-included, pre-wired pipeline — microphone capture → RNNoise denoising → VAD segmentation → Whisper ASR → speaker diarization → live captions / WAV / FLAC / subtitles — delivered as a single C++ SDK with Python bindings, a CLI, and an MCP server that lets AI agents (Claude and others) transcribe audio out of the box — all in one pip install or cmake build.
诚实定位: ffvoice 是一个集成层,而非新的 ASR 引擎。它内嵌 whisper.cpp,不修改其识别精度或推理速度。ffvoice 带来的是一条开箱即用、预连接的完整管道——麦克风采集 → RNNoise 降噪 → VAD 分段 → Whisper ASR → 说话人分离 → 实时字幕 / WAV / FLAC / 字幕输出——打包成 C++ SDK + Python 绑定 + CLI,外加一个 MCP server,让 AI agent(Claude 等)开箱即用地转写音频——一条 pip install 或 cmake 即可完成。
Pain points it addresses / 解决的痛点
| Pain point | ffvoice approach |
|---|---|
| Privacy / 隐私合规 — audio must not leave the device (GDPR, HIPAA, enterprise policy) | 100% offline; audio never transmitted |
| Cloud cost / 云端费用 — commercial APIs charge per minute ($0.01–0.024/min at scale) | Zero per-minute cost; runs on your own hardware |
| Glue code / 胶水代码 — wiring PortAudio + RNNoise + VAD + whisper.cpp + FLAC yourself takes days | All wired together and tested; one SDK |
| Offline / 断网场景 — embedded systems, air-gapped environments, poor connectivity | Fully offline; no network dependency |
| Local responsiveness / 本地响应 — cloud round-trips add network variance | Capture and inference stay on-device; measure end-to-end latency on your target hardware |
What ffvoice does NOT do / 不做什么
- ffvoice does not improve whisper.cpp's WER (word error rate) or speed. If Whisper tiny gives you 12% WER, ffvoice will too.
- ffvoice does not outperform sherpa-onnx or other optimized inference runtimes on raw transcription speed.
- ffvoice does not provide custom vocabulary or acoustic model fine-tuning.
If raw ASR accuracy or throughput is your primary concern, evaluate whisper.cpp directly or consider specialized runtimes. ffvoice's value is the integrated pipeline, not the ASR engine itself.
📋 项目介绍
ffvoice-engine 是一个轻量级、高性能的音频处理引擎,专注于实时音频采集、智能处理和语音识别。
🎯 使用场景
- 📝 会议记录 - 实时转写会议内容,说话人分离标注"谁说了什么",自动生成字幕
- 🎓 在线教育 - 录制课程并生成字幕,支持多语言识别
- 🎙️ 播客制作 - 高质量音频录制 + RNNoise 降噪 + 自动字幕生成
- 🎵 音乐制作 - 低延迟音频采集,支持 FLAC 无损压缩
- 🤖 语音助手 - 实时语音识别和处理,构建本地 AI 语音应用
- 📡 直播字幕 - 边录边转写,生成实时字幕流
✨ 核心优势
vs 商业服务(Azure/Google Cloud Speech):
- ✅ 完全离线 - 无需网络,保护隐私,零 API 费用
- ✅ 本地处理 - 无网络往返;端到端延迟取决于设备、模型与音频长度
- ✅ 开源免费 - MIT 协议,可商用
vs FFmpeg 命令行:
- ✅ 实时转写 - 边录边识别,支持 VAD 智能分段
- ✅ AI 降噪 - 集成 RNNoise 深度学习降噪
- ✅ C++ SDK - 可嵌入任何 C++ 应用,非黑盒工具
vs Python 方案(whisper-cli):
- ✅ 原生管道 - C++20 实现,处理链无 Python 解释器与胶水开销
- ✅ 易部署 - 单一可执行文件,无 Python 环境依赖
- ✅ 同样的精度 - 内嵌 whisper.cpp,识别质量与上游一致(ffvoice 不改模型)
💡 技术亮点
- 🚀 零拷贝处理链 - 音频数据在内存中就地处理
- 🧠 智能 VAD 分段 - 基于 RNNoise VAD 的语音活动检测
- 🎯 高压缩比 - FLAC 无损压缩 2-3x,质量无损
- ⚡ whisper.cpp 推理 - 内嵌 whisper.cpp,Apple Silicon 上推理快于实时
核心特性
- ✅ 实时音频采集 - 低延迟麦克风/系统声音捕获 (PortAudio)
- ✅ 多格式输出 - WAV、FLAC 无损压缩
- ✅ 音频增强处理 - 音量归一化、高通滤波、RNNoise 降噪
- ✅ 离线语音识别 - Whisper ASR (tiny model,纯文本/SRT/VTT/JSON 四种格式,含词级时间戳)
- 🧪 滚动字幕流 - LiveCaptioner 输出 partial/final 事件;partial 会重复转写累计语音,不等同于增量流式解码
- ✅ 说话人分离 - Diarizer 离线 diarization(sherpa-onnx),自动标注"谁在何时说话"
- ✅ Agent 集成 - CLI + MCP server,AI agent 可直接调用本地离线语音能力
🏗️ 当前状态 (v0.8.3)
四个集成层路线图阶段全部交付,已发布到 PyPI(macOS / Linux / Windows,Python 3.10–3.14)。
| 能力 | 状态 |
|---|---|
| 音频采集 / WAV·FLAC 输出 / 音频增强(归一化·高通·RNNoise) | ✅ |
| 离线语音识别(Whisper ASR — 纯文本 / SRT / VTT / JSON,词级时间戳) | ✅ |
| 滚动字幕流(LiveCaptioner — partial/final 字幕事件) | 🧪 实验性;需监控丢样 |
说话人分离(Diarizer — sherpa-onnx,可选 -DENABLE_DIARIZATION=ON) | ✅ |
| Agent 集成(CLI 硬化 + MCP server,5 个工具) | ✅ |
| 当前测试套件:296 C++ + 146 Python,全部通过 | ✅ |
完整历史见 CHANGELOG.md。
🚀 快速开始
依赖
- CMake 3.20+
- C++20 编译器(GCC 10+, Clang 12+, MSVC 2019+)
- FFmpeg 4.4+ (libavcodec, libavformat, libavutil, libswresample)
- PortAudio 19.7+ (音频采集)
- FLAC 1.5+ (无损压缩)
- whisper.cpp (可选,自动下载,用于语音识别)
- RNNoise (可选,自动下载,用于深度学习降噪)
macOS 安装:
brew install cmake ffmpeg portaudio flac
Linux (Ubuntu/Debian) 安装:
sudo apt-get install cmake build-essential \
  libavcodec-dev libavformat-dev libavutil-dev libswresample-dev \
  portaudio19-dev libflac-dev
Windows 安装:
# 使用 vcpkg 管理 C++ 依赖
# 1. 克隆 vcpkg(如果还没有)
git clone https://github.com/Microsoft/vcpkg.git C:\vcpkg
C:\vcpkg\bootstrap-vcpkg.bat

# 2. 安装依赖包
C:\vcpkg\vcpkg install ffmpeg:x64-windows portaudio:x64-windows libflac:x64-windows

# 3. 设置环境变量(用于 CMake)
set CMAKE_TOOLCHAIN_FILE=C:\vcpkg\scripts\buildsystems\vcpkg.cmake

# 注意:Windows 用户也可以直接使用 PyPI 的预编译 wheels(推荐)
# pip install ffvoice
编译
标准编译:
Linux/macOS:
mkdir build && cd build
cmake .. -DCMAKE_BUILD_TYPE=Release
make -j$(nproc)
Windows:
mkdir build
cd build
cmake .. -DCMAKE_BUILD_TYPE=Release -DCMAKE_TOOLCHAIN_FILE=C:\vcpkg\scripts\buildsystems\vcpkg.cmake
cmake --build . --config Release
启用 RNNoise 降噪 (推荐,自动下载):
Linux/macOS:
mkdir build && cd build
cmake .. -DCMAKE_BUILD_TYPE=Release -DENABLE_RNNOISE=ON
make -j$(nproc)
# RNNoise 库会通过 CMake FetchContent 自动下载和编译
Windows:
# 注意:Windows 版本禁用 RNNoise(MSVC 不支持 VLA)
# 使用其他音频处理选项替代
启用 Whisper 语音识别 (推荐,自动下载):
Linux/macOS:
mkdir build && cd build
cmake .. -DCMAKE_BUILD_TYPE=Release -DENABLE_WHISPER=ON
make -j$(nproc)
# whisper.cpp 和 tiny 模型(39MB)会自动下载
Windows:
mkdir build
cd build
cmake .. -DCMAKE_BUILD_TYPE=Release -DENABLE_WHISPER=ON -DCMAKE_TOOLCHAIN_FILE=C:\vcpkg\scripts\buildsystems\vcpkg.cmake
cmake --build . --config Release
启用所有可选功能 (Linux/macOS):
cmake .. -DCMAKE_BUILD_TYPE=Release \
  -DENABLE_RNNOISE=ON \
  -DENABLE_WHISPER=ON
make -j$(nproc)
使用
注意:
- Linux/macOS: 使用
./build/ffvoice- Windows: 使用
.\build\Release\ffvoice.exe
# 查看帮助
./build/ffvoice --help

# 生成测试 WAV 文件(440Hz A4 音符,3秒)
./build/ffvoice --test-wav test.wav

# 列出可用音频设备
./build/ffvoice --list-devices

# 录制 10 秒 WAV 音频(默认格式)
./build/ffvoice --record -o recording.wav -t 10

# 录制 30 秒 FLAC 音频(无损压缩)
./build/ffvoice --record -o recording.flac -t 30

# 使用最大压缩级别录制 FLAC
./build/ffvoice --record -o recording.flac --compression 8 -t 60

# 选择特定设备录制立体声
./build/ffvoice --record -d 1 -o stereo.wav --channels 2 -t 20

# 启用音频处理(音量归一化 + 高通滤波)
./build/ffvoice --record -o clean.wav --enable-processing -t 10

# 仅启用音量归一化
./build/ffvoice --record -o normalized.wav --normalize -t 10

# 自定义高通滤波频率(去除 100Hz 以下噪声)
./build/ffvoice --record -o filtered.flac --highpass 100 -t 20

# 组合:FLAC + 音频处理
./build/ffvoice --record -o studio.flac --normalize --highpass 80 -t 30

# RNNoise 深度学习降噪(推荐用于语音录制,仅 Linux/macOS)
./build/ffvoice --record -o clean.wav --rnnoise -t 10

# 完整处理链(高通 + RNNoise + 归一化,仅 Linux/macOS)
./build/ffvoice --record -o studio.flac --highpass 80 --rnnoise --normalize -t 30

# RNNoise + VAD (实验性,仅 Linux/macOS)
./build/ffvoice --record -o vad.wav --rnnoise-vad -t 20

# 播放录音
afplay recording.wav   # 或 recording.flac

# ==================== 语音识别(需启用 ENABLE_WHISPER) ====================

# 转写音频文件为纯文本
./build/ffvoice --transcribe recording.wav -o transcript.txt

# 生成 SRT 字幕文件
./build/ffvoice --transcribe recording.wav --format srt -o subtitles.srt

# 生成 VTT 字幕文件
./build/ffvoice --transcribe recording.wav --format vtt -o subtitles.vtt

# 生成 JSON 转写文件(含分段级与词级时间戳)
./build/ffvoice --transcribe recording.wav --format json -o transcript.json

# 指定语言(中文)
./build/ffvoice --transcribe recording.wav --language zh -o transcript_zh.txt

# 转写 FLAC 文件
./build/ffvoice --transcribe recording.flac --format srt -o subtitles.srt

# 完整工作流:录制 + 音频处理 + 转写
./build/ffvoice --record -o speech.flac --highpass 80 --rnnoise --normalize -t 30
./build/ffvoice --transcribe speech.flac --format srt -o speech.srt

# ==================== 实时语音识别(需启用 ENABLE_RNNOISE 和 ENABLE_WHISPER) ====================

# 边录边转写(实时模式)
./build/ffvoice --record -o speech.wav --rnnoise-vad --transcribe-live -t 60

# 实时转写 + 音频处理
./build/ffvoice --record -o speech.flac --rnnoise-vad --transcribe-live --highpass 80 --normalize -t 120

# ==================== 实时字幕流(需启用 ENABLE_WHISPER;LiveCaptioner) ====================

# 边说边出字幕:partial 字幕实时刷新,final 字幕断句落定
./build/ffvoice --record -o talk.wav --live-captions -t 60

# 调整 partial 字幕刷新间隔(毫秒)
./build/ffvoice --record -o talk.wav --live-captions --partial-interval 300 -t 60

# ==================== 说话人分离(需 -DENABLE_DIARIZATION=ON 构建) ====================

# 转写并标注说话人:每段带 speaker_id(JSON 输出可见)
./build/ffvoice --transcribe meeting.wav --diarize --format json -o meeting.json

# 指定说话人数量(默认自动判定)
./build/ffvoice --transcribe meeting.wav --diarize --num-speakers 2 --format srt -o meeting.srt
⚠️ LiveCaptioner 边界:音频采集/VAD 已与 Whisper 推理解耦,并由有界队列提供 final 优先、generation 取消、whisper.cpp 协作式计算中止和旧结果抑制;
reset()可在停止后复用已加载模型。partial 仍是重转写累计语音,不是增量解码。SDK/Python 使用方必须同时检查 input drop、cancel、inference job drop、final job drop;任何 final drop 都应视为会话完整性失败。真实设备延迟与打断仍待验证。
⚠️ 说话人分离适用边界:diarization 的 embedding 模型默认英文调优。中文或混合语言音频请改用内置的中英双语模型 —— 在
transcribe_file_with_diarizationMCP 工具(或make_diarizer)传embedding="multilingual",首次使用自动下载。已知说话人数时请传--num-speakers N,自动判定数量在多说话人场景不够稳。
🐍 Python Bindings
ffvoice 提供高性能的 Python 绑定,让您在 Python 中轻松使用所有功能。
安装
从 PyPI 安装 (推荐):
pip install ffvoice                    # 核心:转写 / VAD / 采集 / 混音
pip install 'ffvoice[mcp]'             # + MCP server(供 AI agent 调用)
pip install 'ffvoice[diarization]'     # + 说话人分离(零编译、全平台)
💡 说话人分离免编译:
[diarization]extra 经sherpa-onnx提供 diarization,无需从源码构建 ONNX Runtime;Whisper 与 diarization 模型在首次使用时自动下载到~/.cache/ffvoice/,无需手动配置。
从源码安装:
git clone https://github.com/chicogong/ffvoice-engine.git
cd ffvoice-engine
pip install .
平台兼容性
| 平台 | PyPI Wheel | 安装方式 | 状态 |
|---|---|---|---|
| 🍎 Apple Silicon (M1/M2/M3) | ✅ ARM64 | pip install ffvoice | ✅ 原生支持 |
| 🍎 Intel Mac | ❌ 不兼容 | 从源码编译 | ⚠️ 需手动构建 |
| 🐧 Linux x86_64 | ✅ x86_64 | pip install ffvoice | ✅ 原生支持 |
| 🪟 Windows x86_64 | ✅ x86_64 | pip install ffvoice | ✅ 原生支持 |
重要说明:
- Apple Silicon 用户: 直接使用
pip install ffvoice即可,性能最佳 - Windows 用户: 现已支持 Windows x86_64 预编译 wheels,直接使用
pip install ffvoice即可- 支持 Python 3.10-3.14
- 自动包含所有必需的依赖(无需手动安装 FFmpeg 等)
- 注意: Windows 版本禁用了 RNNoise 降噪(MSVC 不支持 VLA),其他功能完全可用
- Intel Mac 用户: PyPI wheel 不兼容,需要从源码编译:
# 确保已安装依赖 brew install cmake ffmpeg portaudio flac # 从源码安装 git clone https://github.com/chicogong/ffvoice-engine.git cd ffvoice-engine pip install . - Rosetta 2 用户: ARM64 wheel 在 Rosetta 环境下不工作,请使用 ARM64 原生 Python:
# 检查 Python 架构
python -c "import platform; print(platform.machine())"
# 应该输出 'arm64',如果是 'x86_64' 则需要重新安装 ARM64 Python

# 强制使用 ARM64 Python
arch -arm64 python3 -m pip install ffvoice
快速示例
import ffvoice
import numpy as np

# 1. 语音识别
config = ffvoice.WhisperConfig()
config.model_type = ffvoice.WhisperModelType.TINY
asr = ffvoice.WhisperASR(config)
asr.initialize()

# 从文件转写
segments = asr.transcribe_file("audio.wav")
for seg in segments:
    print(f"[{seg.start_ms}ms - {seg.end_ms}ms] {seg.text}")

# 从 NumPy 数组转写
audio = np.zeros(48000, dtype=np.int16)  # 1秒音频
segments = asr.transcribe_buffer(audio)

# 2. 噪声抑制
rnnoise = ffvoice.RNNoise(ffvoice.RNNoiseConfig())
rnnoise.initialize(sample_rate=48000, channels=1)

audio = np.random.randint(-1000, 1000, 256, dtype=np.int16)
rnnoise.process(audio)  # 原地处理
vad_prob = rnnoise.get_vad_probability()

# 3. 实时音频采集
def audio_callback(audio_array):
    print(f"收到 {len(audio_array)} 个采样")

ffvoice.AudioCapture.initialize()
capture = ffvoice.AudioCapture()
capture.open(sample_rate=48000, channels=1, frames_per_buffer=256)
capture.start(audio_callback)
# ... 录制中 ...
capture.stop()
capture.close()
ffvoice.AudioCapture.terminate()

# 4. 多音轨混音
mixer = ffvoice.AudioMixer()
mixer.initialize(sample_rate=48000, channels=2)
track = mixer.add_track(gain=1.0, pan=0.0)
mixed = mixer.mix_block({track: np.zeros(480, dtype=np.int16)})

# 5. 无锁环形缓冲区(实时音频路径的线程间交接)
ring = ffvoice.RingBuffer(capacity=4096)
ring.push_bulk(np.zeros(1024, dtype=np.int16))
chunk = ring.pop_bulk(512)

# 6. 词级时间戳
config.word_timestamps = True  # 转写结果的每个分段附带 words 数组
for seg in asr.transcribe_file("audio.wav"):
    for word in seg.words:
        print(f"  [{word.start_ms}-{word.end_ms}ms] {word.text}")
完整文档
详细文档和示例请查看 python/README.md:
- 📖 完整 API 参考(含
AudioMixer多音轨混音、RingBuffer无锁环形缓冲区、词级时间戳Word/TranscriptionSegment.words) - 🎯 16+ 代码示例
- 🚀 Quick Start 指南
- 📓 Jupyter Notebook 教程
性能优势:
- ⚡ 3-10x 更快 - C++ 核心 vs 纯 Python 实现
- 💾 零拷贝 - NumPy 数组直接传递
- 🔒 100% 离线 - 无需网络,隐私安全
- 🎙️ 完整工作流 - 采集 → 降噪 → VAD → 识别
🤖 AI Agent 集成 — MCP Server + Agent Skill
ffvoice 内置了一个 MCP (Model Context Protocol) 服务器,让 AI agent(如 Claude Desktop)能够直接调用本地离线语音识别能力,全程无需联网,音频数据绝不离开本机。
安装
pip install 'ffvoice[mcp]'                # MCP server
pip install 'ffvoice[mcp,diarization]'    # + 说话人分离工具
提供的工具
| 工具 | 说明 |
|---|---|
transcribe_file | 转写本地音频文件(WAV/FLAC 等),支持语言选择、模型大小、词级时间戳 |
transcribe_file_with_diarization | 转写并标注说话人 —— 每段带 speaker_id,回答"谁在何时说什么"(需 pip install 'ffvoice[diarization]',免编译) |
capture_and_transcribe | 录制指定时长的麦克风音频并实时转写(内置 VAD 分段 + 可选 RNNoise 降噪) |
capture_and_caption | 录制麦克风音频并产出实时字幕流(LiveCaptioner,partial/final 事件) |
list_audio_devices | 列出所有可用的音频输入/输出设备及默认设备 ID |
接入 Claude Desktop
将以下配置粘贴到 Claude Desktop 的 claude_desktop_config.json:
{"mcpServers": {"ffvoice": {"command": "ffvoice-mcp", "args": []}}}
重启 Claude Desktop 后,即可在对话中直接请求转写本地音频或录制语音。
Claude Agent Skill
仓库内置一个 Claude Agent Skill(.claude/skills/ffvoice-transcription/)—— 用 Claude Code 打开本仓库即被自动发现,无需任何配置。它教 agent 何时、如何用 ffvoice 的 MCP 工具与 CLI 完成转写、说话人分离、实时字幕。配合 MCP server,ffvoice 对 AI agent 真正做到开箱即用。
📁 项目结构
ffvoice-engine/
├── CMakeLists.txt          # 主构建文件
├── include/ffvoice/        # 公共头文件
│   └── types.h             # 核心类型定义
├── src/                    # 源代码
│   ├── audio/              # 音频采集与处理模块
│   │   ├── audio_capture_device.* # ✅ PortAudio 采集器
│   │   ├── audio_mixer.*          # ✅ 多音轨混音器
│   │   ├── audio_processor.*      # ✅ 音频处理框架
│   │   ├── rnnoise_processor.*    # ✅ RNNoise 深度学习降噪 (可选)
│   │   ├── vad_segmenter.*        # ✅ VAD 音频分段器
│   │   ├── whisper_processor.*    # ✅ Whisper ASR 语音识别 (可选)
│   │   ├── live_captioner.*       # ✅ 实时字幕流 LiveCaptioner (可选)
│   │   └── diarizer.*             # ✅ 说话人分离 Diarizer (可选)
│   ├── media/              # 媒体编码/封装
│   │   ├── wav_writer.*    # ✅ WAV 文件写入器
│   │   └── flac_writer.*   # ✅ FLAC 无损压缩
│   └── utils/              # 工具类
│       ├── signal_generator.* # ✅ 音频信号生成
│       ├── ring_buffer.*   # ✅ 环形缓冲区
│       ├── audio_converter.*  # ✅ 音频格式转换
│       ├── subtitle_generator.* # ✅ 字幕生成(SRT/VTT)
│       └── logger.*        # ✅ 日志工具
├── apps/cli/               # CLI 应用
│   └── main.cpp            # ✅ 完整录音功能
├── tests/                  # 单元测试
│   ├── unit/               # ✅ 当前 296 个 C++ 测试(全部通过)
│   ├── mocks/              # Mock 对象
│   └── fixtures/           # 测试夹具
├── models/                 # AI 模型文件
└── scripts/                # 辅助脚本
🛣️ 路线图
Milestone 1–6 —— 基础录制 → 音频增强(RNNoise) → 离线 ASR(Whisper) → 实时 ASR → 性能优化 → AudioMixer / RingBuffer / 词级时间戳 —— ✅ 全部完成。
集成层路线图(v0.8.3):
- ✅ Phase 1 Agent 集成 — CLI 硬化 + MCP server,让 AI agent 把 ffvoice 当本地离线语音工具调用;v0.7.0 已发布到 PyPI
- 🧪 Phase 2 滚动字幕流 — LiveCaptioner 已有 partial/final 事件;真正低延迟对话接入仍需异步推理、取消与积压观测
- ✅ Phase 3 说话人分离 — Diarizer(sherpa-onnx 离线 diarization),CLI
--diarize+ MCPtranscribe_file_with_diarization
下一阶段:面向 Open Voice Agent 的稳定输入层
- ✅ v0.8.4 正确性与可观测性 — 采样率一致性、mono 合同、丢样计数、类型桩。
- 🧪 v0.9 对话流式核心 — 已完成采集/VAD 与 Whisper 解耦、有界任务队列、final 优先、generation 取消、会话 reset,以及 backlog/drop/queue-wait/final-latency 指标;尚缺 whisper.cpp 在途计算中止与真实设备端点验证。
- v1.0 采用门槛 — 真实设备语料上的 WER、RTF、端点延迟、丢样基线;验证 wheel 矩阵;由 Open Voice Agent 通过稳定 provider 合同消费。
完整历史见 CHANGELOG.md。
📝 开发说明
主分支:master
代码规范
- C++20 标准
- Google C++ Style Guide(部分)
- 使用 clang-format 格式化
测试
# 配置并编译测试
cmake .. -DBUILD_TESTS=ON -DCMAKE_BUILD_TYPE=Debug
make -j4

# 运行所有测试
make test

# 运行单个测试(详细输出)
./build/tests/ffvoice_tests --gtest_filter=WavWriter*
已实现功能
AudioCaptureDevice - 音频采集器
- 基于 PortAudio 的跨平台音频捕获
- 实时流式采集(回调模式)
- 设备枚举和自动选择
- 低延迟配置(256 帧缓冲)
- 支持 mono/stereo
- 可配置采样率(默认 48kHz)
WavWriter - WAV 文件写入器
- 手写 RIFF/WAV 格式实现
- 支持 PCM 16-bit 音频
- 支持 mono/stereo
- 可调采样率
- 实时写入支持
FlacWriter - FLAC 无损压缩
- 基于 libFLAC 1.5.0
- 实时流式编码
- 可配置压缩级别(0-8,默认 5)
- 压缩比 1.5-3x(取决于音频内容)
- 支持 16/24-bit PCM
- 自动压缩比统计
SignalGenerator - 音频信号生成器
- 正弦波生成(可调频率、时长、振幅)
- 静音生成
- 白噪声生成
- 用于测试和调试
AudioProcessor - 音频处理框架
架构设计:
- 抽象接口
AudioProcessor支持模块化扩展 AudioProcessorChain处理器链(串联多个处理器)- 实时处理(在采集回调中)
- 就地处理(in-place)提高效率
VolumeNormalizer - 音量归一化:
- 基于 RMS 的自动增益控制
- 平滑增益调整(exponential moving average)
- Attack time: 0.1s(增益提升速度)
- Release time: 0.3s(增益下降速度)
- 目标电平:0.3(可配置 0.0-1.0)
- 增益范围:0.1x - 10.0x
- 防止削波和保持一致响度
HighPassFilter - 高通滤波器:
- 一阶 IIR 滤波器实现
- 去除低频噪声(呼吸声、麦克风碰撞、环境噪音)
- 默认截止频率:80Hz(可配置)
- 每通道独立状态(支持立体声)
- 滤波器公式:
y[n] = α(y[n-1] + x[n] - x[n-1])
RNNoiseProcessor - RNNoise 深度学习降噪 (可选):
- 基于 Xiph RNNoise 的 RNN 深度学习模型
- 专为语音优化的降噪算法
- 帧大小:480 samples (10ms @48kHz)
- 支持采样率:48kHz, 44.1kHz, 24kHz
- 多声道支持:每通道独立 DenoiseState
- 格式转换:自动处理 int16 ↔ float
- 帧缓冲管理:256 samples → 480 samples
- VAD 选项:可选语音活动检测(实验性)
- CPU 开销:~5-10%(显著低于 WebRTC APM)
- 降噪效果:~20dB(语音场景)
性能:
- 实时处理(<10ms 延迟)
- 低 CPU 开销(RNNoise: ~8%)
- 支持 mono/stereo
WhisperProcessor - 离线语音识别 (可选)
- 基于 OpenAI Whisper 的 C++ 实现 (whisper.cpp)
- 自动下载和集成 tiny 模型(39MB)
- 支持多种语言识别(中文、英文、自动检测)
- 音频格式自动转换(WAV/FLAC → 16kHz float mono)
- 四种输出格式:
- 纯文本(无时间戳)
- SRT 字幕(SubRip 格式)
- VTT 字幕(WebVTT 格式)
- JSON 转写(含分段级与词级时间戳 / per-segment & per-word timestamps)
- 词级时间戳(word-level timestamps):每个分段附带
words数组,每个词有独立的起止时间与概率(WhisperConfig::word_timestamps) - 性能指标(Apple M3 Pro, Rosetta 2):
- 转写速度:5-75x realtime(取决于音频长度)
- 内存占用:~272MB(模型 + 计算缓冲区)
- 准确率:英文 ~8-10% WER,中文 ~12-15% WER
- 推理线程数可配置(默认 4 线程)
- 可选翻译功能(转写 + 翻译成英文)
性能优化(v0.3.0 新增):
- Whisper 模型选择:
- 支持 TINY/BASE/SMALL/MEDIUM/LARGE 模型
- 灵活平衡速度与精度(10x → 0.5x realtime)
- 性能计时系统:
- 详细分段计时(转换/推理/提取)
- 实时因子 (RTF) 自动计算
- 性能瓶颈识别
- VAD 智能优化:
- 5 种灵敏度预设(VERY_SENSITIVE → VERY_CONSERVATIVE)
- 自适应阈值调整(根据环境噪声动态优化)
- 实时统计(平均 VAD 概率、语音占比)
- 内存优化:
- 缓冲区重用(减少 90% 内存分配)
- 条件扩容(避免不必要的 resize)
- 降低内存碎片化和 GC 压力
AudioConverter - 音频格式转换:
- WAV/FLAC 文件加载
- 采样率转换(48kHz/44.1kHz → 16kHz)
- 格式转换(int16 → float)
- 声道转换(stereo → mono)
- 线性插值重采样
SubtitleGenerator - 字幕生成:
- SRT 格式(
00:00:01,500时间戳格式) - VTT 格式(
00:00:01.500时间戳格式 + WEBVTT 头) - 纯文本格式(无时间戳)
- 自动时间戳格式化
测试覆盖
- 当前 296 个 C++ 单元测试 + 146 个 Python 测试,全部通过
- 覆盖音频采集 / 编码(WAV·FLAC)/ 处理(归一化·高通·RNNoise)/ VAD / Whisper ASR / 字幕生成 / LiveCaptioner / Diarizer / AudioMixer / RingBuffer
- C++ 用 Google Test,Python 用 pytest
- CI 矩阵覆盖 Linux / macOS / Windows × Python 3.10–3.14
🤝 贡献 / Contributing
我们欢迎并感谢所有形式的贡献!无论是报告 bug、提出新功能、改进文档还是提交代码,都对项目有很大帮助。
We welcome and appreciate all forms of contributions! Whether it's reporting bugs, proposing new features, improving documentation, or submitting code.
如何贡献 / How to Contribute
- 🐛 报告 Bug - 使用 Bug Report 模板
- ✨ 请求功能 - 使用 Feature Request 模板
- 📝 改进文档 - 提交 PR 改进 README、docs 或代码注释
- 💻 提交代码 - Fork → 开发 → 测试 → PR
开发指南 / Development Guide
详细的贡献指南请参阅 CONTRIBUTING.md
快速开始:
# 1. Fork 并克隆仓库
git clone https://github.com/YOUR_USERNAME/ffvoice-engine.git

# 2. 创建功能分支
git checkout -b feature/your-feature-name

# 3. 进行开发并测试
cmake -B build -DBUILD_TESTS=ON
make -C build -j$(nproc)
make -C build test

# 4. 格式化代码
./scripts/format.sh

# 5. 提交并推送
git commit -m "feat: add your feature"
git push origin feature/your-feature-name

# 6. 创建 Pull Request
代码规范 / Code Style
- 语言: C++20
- 风格指南: Google C++ Style Guide(变体)
- 格式化工具: clang-format(配置见
.clang-format) - 静态分析: clang-tidy(配置见
.clang-tidy) - 提交规范: Conventional Commits
行为准则 / Code of Conduct
请遵守我们的 行为准则,营造友好和包容的社区环境。
Please follow our Code of Conduct to maintain a welcoming and inclusive community environment.
📊 项目状态 / Project Status
- ✅ Milestone 1: 基础音频采集和文件保存 - 完成
- ✅ Milestone 2: 音频处理增强 (RNNoise) - 完成
- ✅ Milestone 3: 离线语音识别 (Whisper ASR) - 完成
- ✅ Milestone 4: 实时语音识别 - 完成
- ✅ Milestone 5: 性能优化与增强 - 完成
- ✅ Milestone 6: 高级功能 (AudioMixer / RingBuffer / 词级时间戳 / JSON 字幕) - 完成
- ✅ 集成层路线图 (v0.8.3): Agent 集成 (CLI + MCP) / 实时字幕流 / 说话人分离 - 完成
详见 CHANGELOG.md
📞 支持与反馈 / Support & Feedback
- 📖 文档: docs/
- 💬 讨论: GitHub Discussions
- 🐛 Bug 报告: GitHub Issues
- 📧 联系: chicogong@tencent.com
📄 许可证 / License
本项目采用 MIT 许可证 - 详见 LICENSE 文件。
This project is licensed under the MIT License - see the LICENSE file for details.
🙏 致谢 / Acknowledgments
感谢以下开源项目:
Thanks to the following open-source projects:
- FFmpeg - 多媒体处理框架
- PortAudio - 跨平台音频 I/O 库
- FLAC - 无损音频压缩
- whisper.cpp - OpenAI Whisper 的 C++ 实现
- RNNoise - 深度学习降噪库
- Google Test - C++ 测试框架
⭐ Star History
如果这个项目对你有帮助,请考虑给我们一个 ⭐ Star!
If this project helps you, please consider giving us a ⭐ Star!
Installation
Source-derived launch command. Check the maintainer’s required arguments and credentials before running:
uvx ffvoiceSet up in your AI client
Merge this template into ~/Library/Application Support/Claude/claude_desktop_config.json. Keep existing servers. Add any arguments, credentials, and permissions required by the maintainer; this template has not been install-tested.
{
  "mcpServers": {
    "io-github-chicogong-ffvoice": {
      "command": "uvx",
      "args": [
        "ffvoice"
      ]
    }
  }
}
Restart Claude Desktop completely for changes to take effect. Confirm the server appears connected in the client’s tool list, then try a read-only example from its documentation.
Claude Desktop setup referencePackage
Compatible MCP Clients
io.github.chicogong/ffvoice works with any MCP-compatible client. Copy the config snippet from the Configuration section above and add it to the file shown for your client, then restart the application.
- Claude Desktop
~/Library/Application Support/Claude/claude_desktop_config.jsonRestart Claude Desktop completely for changes to take effect. - Cursor
~/.cursor/mcp.jsonRestart Cursor for changes to take effect. - VS Code
.vscode/mcp.jsonReload VS Code window for changes to take effect. - Windsurf
~/.codeium/windsurf/mcp_config.jsonRestart Windsurf for changes to take effect. - Claude Code
.mcp.jsonSave at the project root, then start Claude Code in that project and review the MCP server approval prompt. Keep real credentials out of shared files.