datadiffer
Read-only table diffs with segment attribution: which slice of your data changed.
datadiffer
Diff two tables. See what changed, and which slice of your data it's concentrated in.
98.6% of modified rows have country = 'DE' (8.87x over-represented)


datadiffer compares two tables (dev vs. prod, PR vs. main, source vs.
destination) and tells you what changed and where it's concentrated: rows
added / removed / modified, per-column change rates, and segment attribution.
Built for the era when agents write your pipelines and someone has to check their work. A maintained, MIT-licensed successor to the archived data-diff.
Try it in 60 seconds
No credentials, no config, no account. It generates its own data:
uvx datadiffer demo
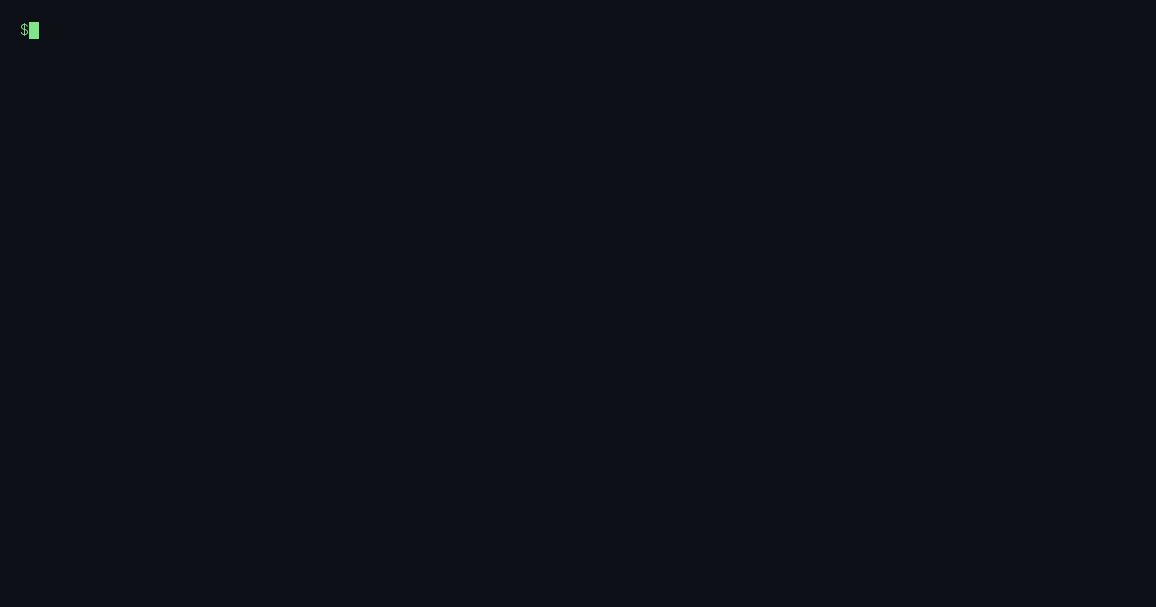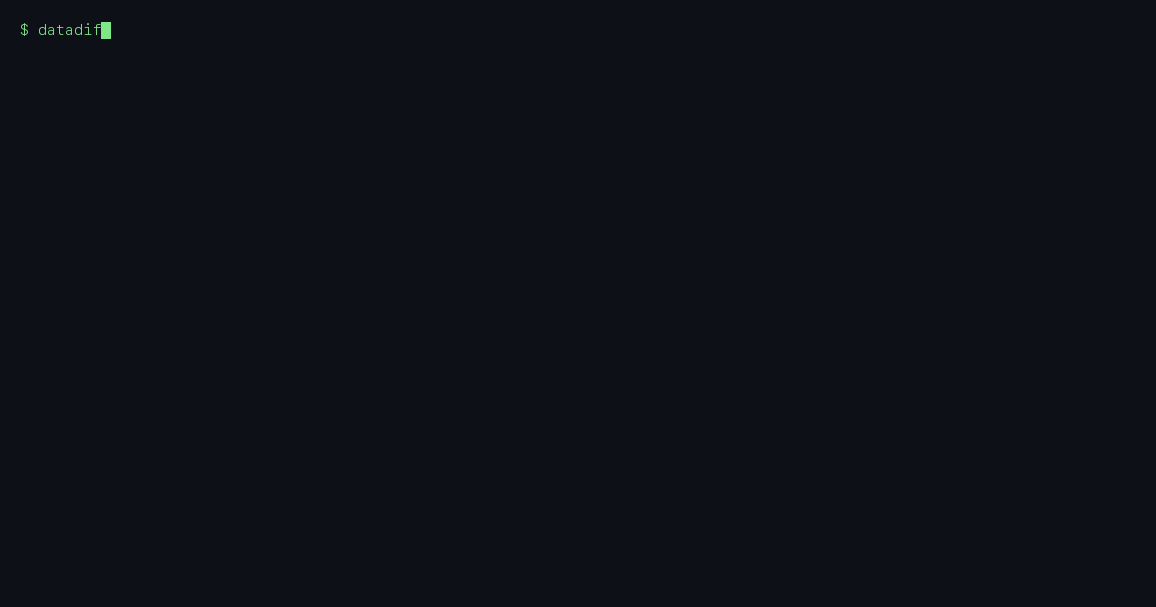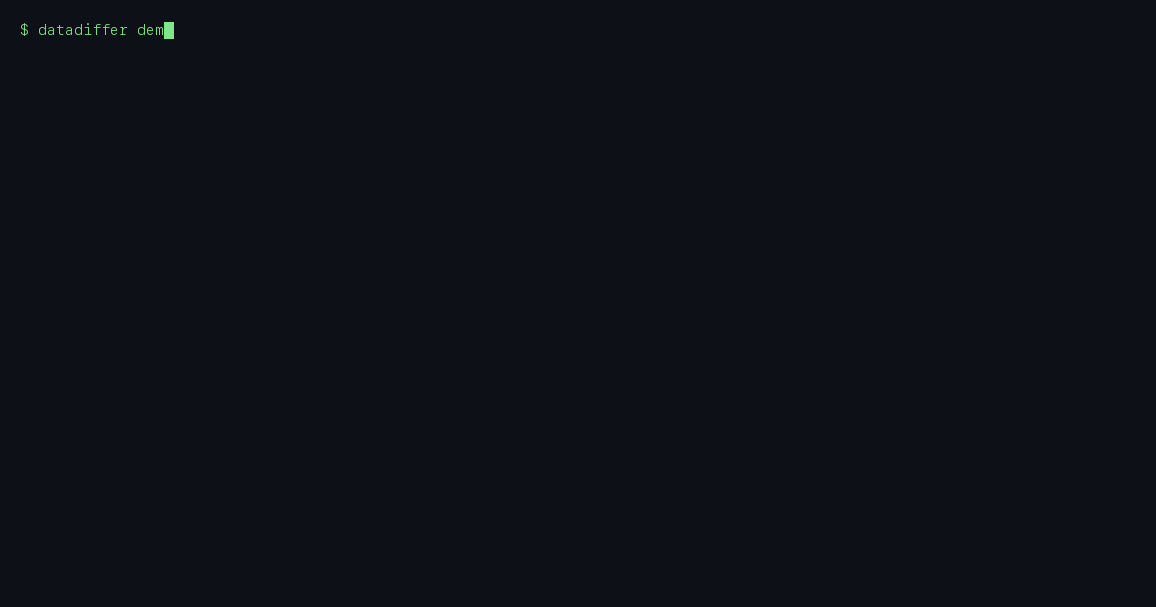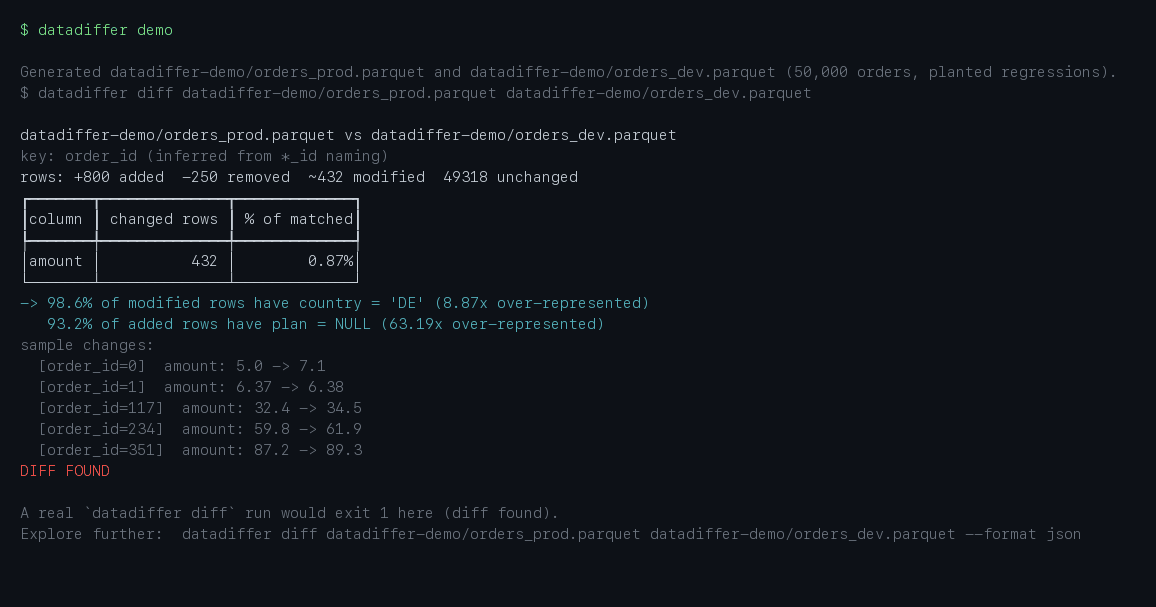
datadiffer-demo/orders_prod.parquet vs datadiffer-demo/orders_dev.parquet
key: order_id (inferred from *_id naming)
rows: +800 added  -250 removed  ~432 modified  49318 unchanged
┏━━━━━━━┳━━━━━━━━━━━━━━┳━━━━━━━━━━━━━┓
┃column ┃ changed rows ┃ % of matched┃
┡━━━━━━━╇━━━━━━━━━━━━━━╇━━━━━━━━━━━━━┩
│amount │          432 │        0.87%│
└───────┴──────────────┴─────────────┘
-> 98.6% of modified rows have country = 'DE' (8.87x over-represented)
   93.2% of added rows have plan = NULL (63.19x over-represented)
sample changes:
  [order_id=0]  amount: 5.0 -> 7.1
  [order_id=1]  amount: 6.37 -> 6.38
  [order_id=117]  amount: 32.4 -> 34.5
  [order_id=234]  amount: 59.8 -> 61.9
  [order_id=351]  amount: 87.2 -> 89.3
DIFF FOUND
That last block is the point. A diff tells you 432 rows changed; datadiffer tells you they're almost all German orders, which is the difference between "something moved" and "the VAT change landed."
Install
pip install datadiffer                      # local files: Parquet, CSV, DuckDB
pip install 'datadiffer[snowflake]'         # + Snowflake
pip install 'datadiffer[postgres]'          # + Postgres
pip install 'datadiffer[mcp]'               # + MCP server for AI agents
Use it
# local files
datadiffer diff prod.parquet dev.parquet

# DuckDB
datadiffer diff prod.duckdb:orders dev.duckdb:orders

# Postgres (attached read-only)
datadiffer diff orders orders_v2 --source "postgresql://user@host:5432/db"

# Snowflake, or anything in datadiffer.toml (run `datadiffer init` first)
datadiffer diff wh::analytics.orders wh::analytics_dev.orders

# cross-source: warehouse vs. a local file
datadiffer diff wh::orders orders_snapshot.parquet

# machine-readable, for scripts and CI
datadiffer diff a.parquet b.parquet --format json
Exit codes follow the GNU diff convention: 0 no differences, 1 differences found, 2 operational error.
Useful flags: --key (inferred when omitted), --where, --columns /
--exclude-columns, --sample-limit, --no-attribution, -q.
In your pull requests
datadiffer-action posts the report as a sticky PR comment:
datadiffer:
ANALYTICS.ORDERSvsANALYTICS_PR_482.ORDERS: differences found ❌+800 added · −250 removed · ~432 modified · 49,318 unchanged (2.96% of base rows affected) Policy: max-changed-rows-pct exceeded: 2.96% > 0.5%
Column Changed rows % of matched amount432 0.87% Where it's concentrated: 98.6% of modified rows have
country = 'DE'(8.87× over-represented) 93.2% of added rows haveplan = NULL(63.19× over-represented)
- uses: gauthierpiarrette/datadiffer-action@v1
  with:
    config: datadiffer.toml          # holds the warehouse connection
    table-a: wh::ANALYTICS.ORDERS
    schema-map: "ANALYTICS=ANALYTICS_PR_${PR_NUMBER}"
    max-changed-rows-pct: "0.5"
  env:
    SNOWFLAKE_PRIVATE_KEY: ${{ secrets.SNOWFLAKE_PRIVATE_KEY }}
Running dbt? docs/dbt-ci.md turns dbt ls --select state:modified into one diff per changed model, each with its own comment.
For AI agents (MCP)
Let a coding agent verify its own data changes:
datadiffer init # scaffold datadiffer.toml, then add the server to your client
{ "mcpServers": { "datadiffer": { "command": "datadiffer", "args": ["mcp"] } } }
Any MCP client works. datadiffer init prints the server entry to paste,
including a uvx form for clients that prefer no global install.
Four read-only tools: list_connections, schema_diff, diff_summary
(cheap preflight), diff_tables (full report). Credentials never pass
through the model. Tools take connection names from your local
datadiffer.toml, never DSNs. Over-cap requests come back as structured
refusals with a remedy, so the agent can self-correct instead of failing.
What makes it different
Most diff tools answer whether two tables match. datadiffer answers what changed and where: which columns moved, and which slice of the data the change is concentrated in.
| Tool | Use it instead when |
|---|---|
| Datafold | You need billion-row cross-database reconciliation, a collaboration UI, lineage/impact analysis, and a support contract. |
SQLMesh table_diff | You already run SQLMesh and diff within a single gateway (cross-database diffing is a Tobiko Cloud feature). |
| Recce | You want a dbt-native PR review UI and your whole workflow is dbt. |
| Google DVT | You're validating a migration across 17 warehouse types and want pass/fail validation with YAML configs. |
| datacompy | You're comparing two pandas/Spark/Polars DataFrames inside one process. |
datadiffer is for the case in between: one command, no platform, works from your terminal, your CI, or your agent, and it explains itself.
Migrating from data-diff / reladiff
Same job, different flags:
| data-diff / reladiff | datadiffer |
|---|---|
data-diff DB1 table1 DB2 table2 | datadiffer diff <a> <b> (locators or --source/--target) |
-k, --key-columns | --key (repeatable, or comma-separated) |
-c, --columns | --columns |
-w, --where | --where (validated: single boolean expression, no subqueries) |
--json | --format json (stable schema v1) |
-l, --limit | --sample-limit |
Differences worth knowing: keys are inferred from declared constraints or
*_id conventions when you omit --key; unknown column names in filters are
an error, never silently ignored; and exit code 1 means "diff found"
(2 is reserved for operational errors), so CI can tell them apart.
Not yet ported: checksum-bisection hashdiff for very large cross-database diffs, which is reladiff's headline capability, plus MySQL, Oracle, ClickHouse, Trino and the rest of its connector list. If you need those today, use reladiff; the bisection port is the top item on our v0.2 roadmap and will credit its author.
Full command mapping and behavior differences: docs/migrating-from-data-diff.md.
Scope and limits (v0.1)
- Warehouses: Snowflake, Postgres, DuckDB, Parquet, CSV. BigQuery is next (v0.1.1).
- Every diff runs in local DuckDB. Postgres is attached read-only and
scanned in place; Snowflake is pulled once over Arrow with only the needed
columns. Both are capped at 50M rows and 10 GiB per side, so narrow the
comparison with
--where. Pushing the comparison into the warehouse, and lifting that cap with checksum bisection, are the next two pieces of work. - Postgres reads are unsnapshotted (the report says so in
execution.snapshot); Snowflake pulls are a single consistent SELECT. - Segment attribution is single-column, categorical, and descriptive. It says "over-represented", never causal.
Project
MIT, no CLA, no telemetry. The report schema is frozen at v1 and contract-tested, so pipelines and agents that parse it keep working across releases. Dependencies are deliberately few: DuckDB, PyArrow, sqlglot, click, rich.
What's next
BigQuery, then checksum-bisection hashdiff so large cross-database diffs stop needing a row cap (ported with credit to reladiff), then more connectors. Tracked in issues. Comment on the one you need and it moves up.
Contributing
git clone https://github.com/gauthierpiarrette/datadiffer && cd datadiffer
uv sync --group dev
uv run pytest -q            # warehouse tests skip unless credentials are set
uv run ruff check .
Prior art gratefully acknowledged: data-diff and reladiff (Erez Shinan), whose checksum-bisection design v0.2 will port; Adtributor (Microsoft Research) for the attribution scoring; and DuckDB, which makes all of this fast enough to be boring.
License
MIT
Installation
Source-derived launch command. Check the maintainer’s required arguments and credentials before running:
uvx datadifferSet up in your AI client
Merge this template into ~/Library/Application Support/Claude/claude_desktop_config.json. Keep existing servers. Add any arguments, credentials, and permissions required by the maintainer; this template has not been install-tested.
{
  "mcpServers": {
    "io-github-gauthierpiarrette-datadiffer": {
      "command": "uvx",
      "args": [
        "datadiffer"
      ]
    }
  }
}
Restart Claude Desktop completely for changes to take effect. Confirm the server appears connected in the client’s tool list, then try a read-only example from its documentation.
Claude Desktop setup referencePackage
datadifferpypiCompatible MCP Clients
datadiffer works with any MCP-compatible client. Copy the config snippet from the Configuration section above and add it to the file shown for your client, then restart the application.
- Claude Desktop
~/Library/Application Support/Claude/claude_desktop_config.jsonRestart Claude Desktop completely for changes to take effect. - Cursor
~/.cursor/mcp.jsonRestart Cursor for changes to take effect. - VS Code
.vscode/mcp.jsonReload VS Code window for changes to take effect. - Windsurf
~/.codeium/windsurf/mcp_config.jsonRestart Windsurf for changes to take effect. - Claude Code
.mcp.jsonSave at the project root, then start Claude Code in that project and review the MCP server approval prompt. Keep real credentials out of shared files.