superPDF AI
PDF tools on your computer: read, convert, edit, merge, fill and compare PDFs. Nothing is uploaded.
superPDF AI: PDF tools that run on your computer, from the command line, Python, AI assistants (MCP) or a local API.
Tables, charts, headings and scans to Markdown, HTML or JSON; Word, Excel and PowerPoint; forms, merging and comparing. The reader works by rules, not a language model; scans go through Tesseract OCR. Nothing is uploaded.



Website · Docs · Python docs · Benchmark · Changelog
How it compares · Quick start · JavaScript/TypeScript · Python · MCP tools · How it works
npx @superpdf/cli export report.pdf --output report.md
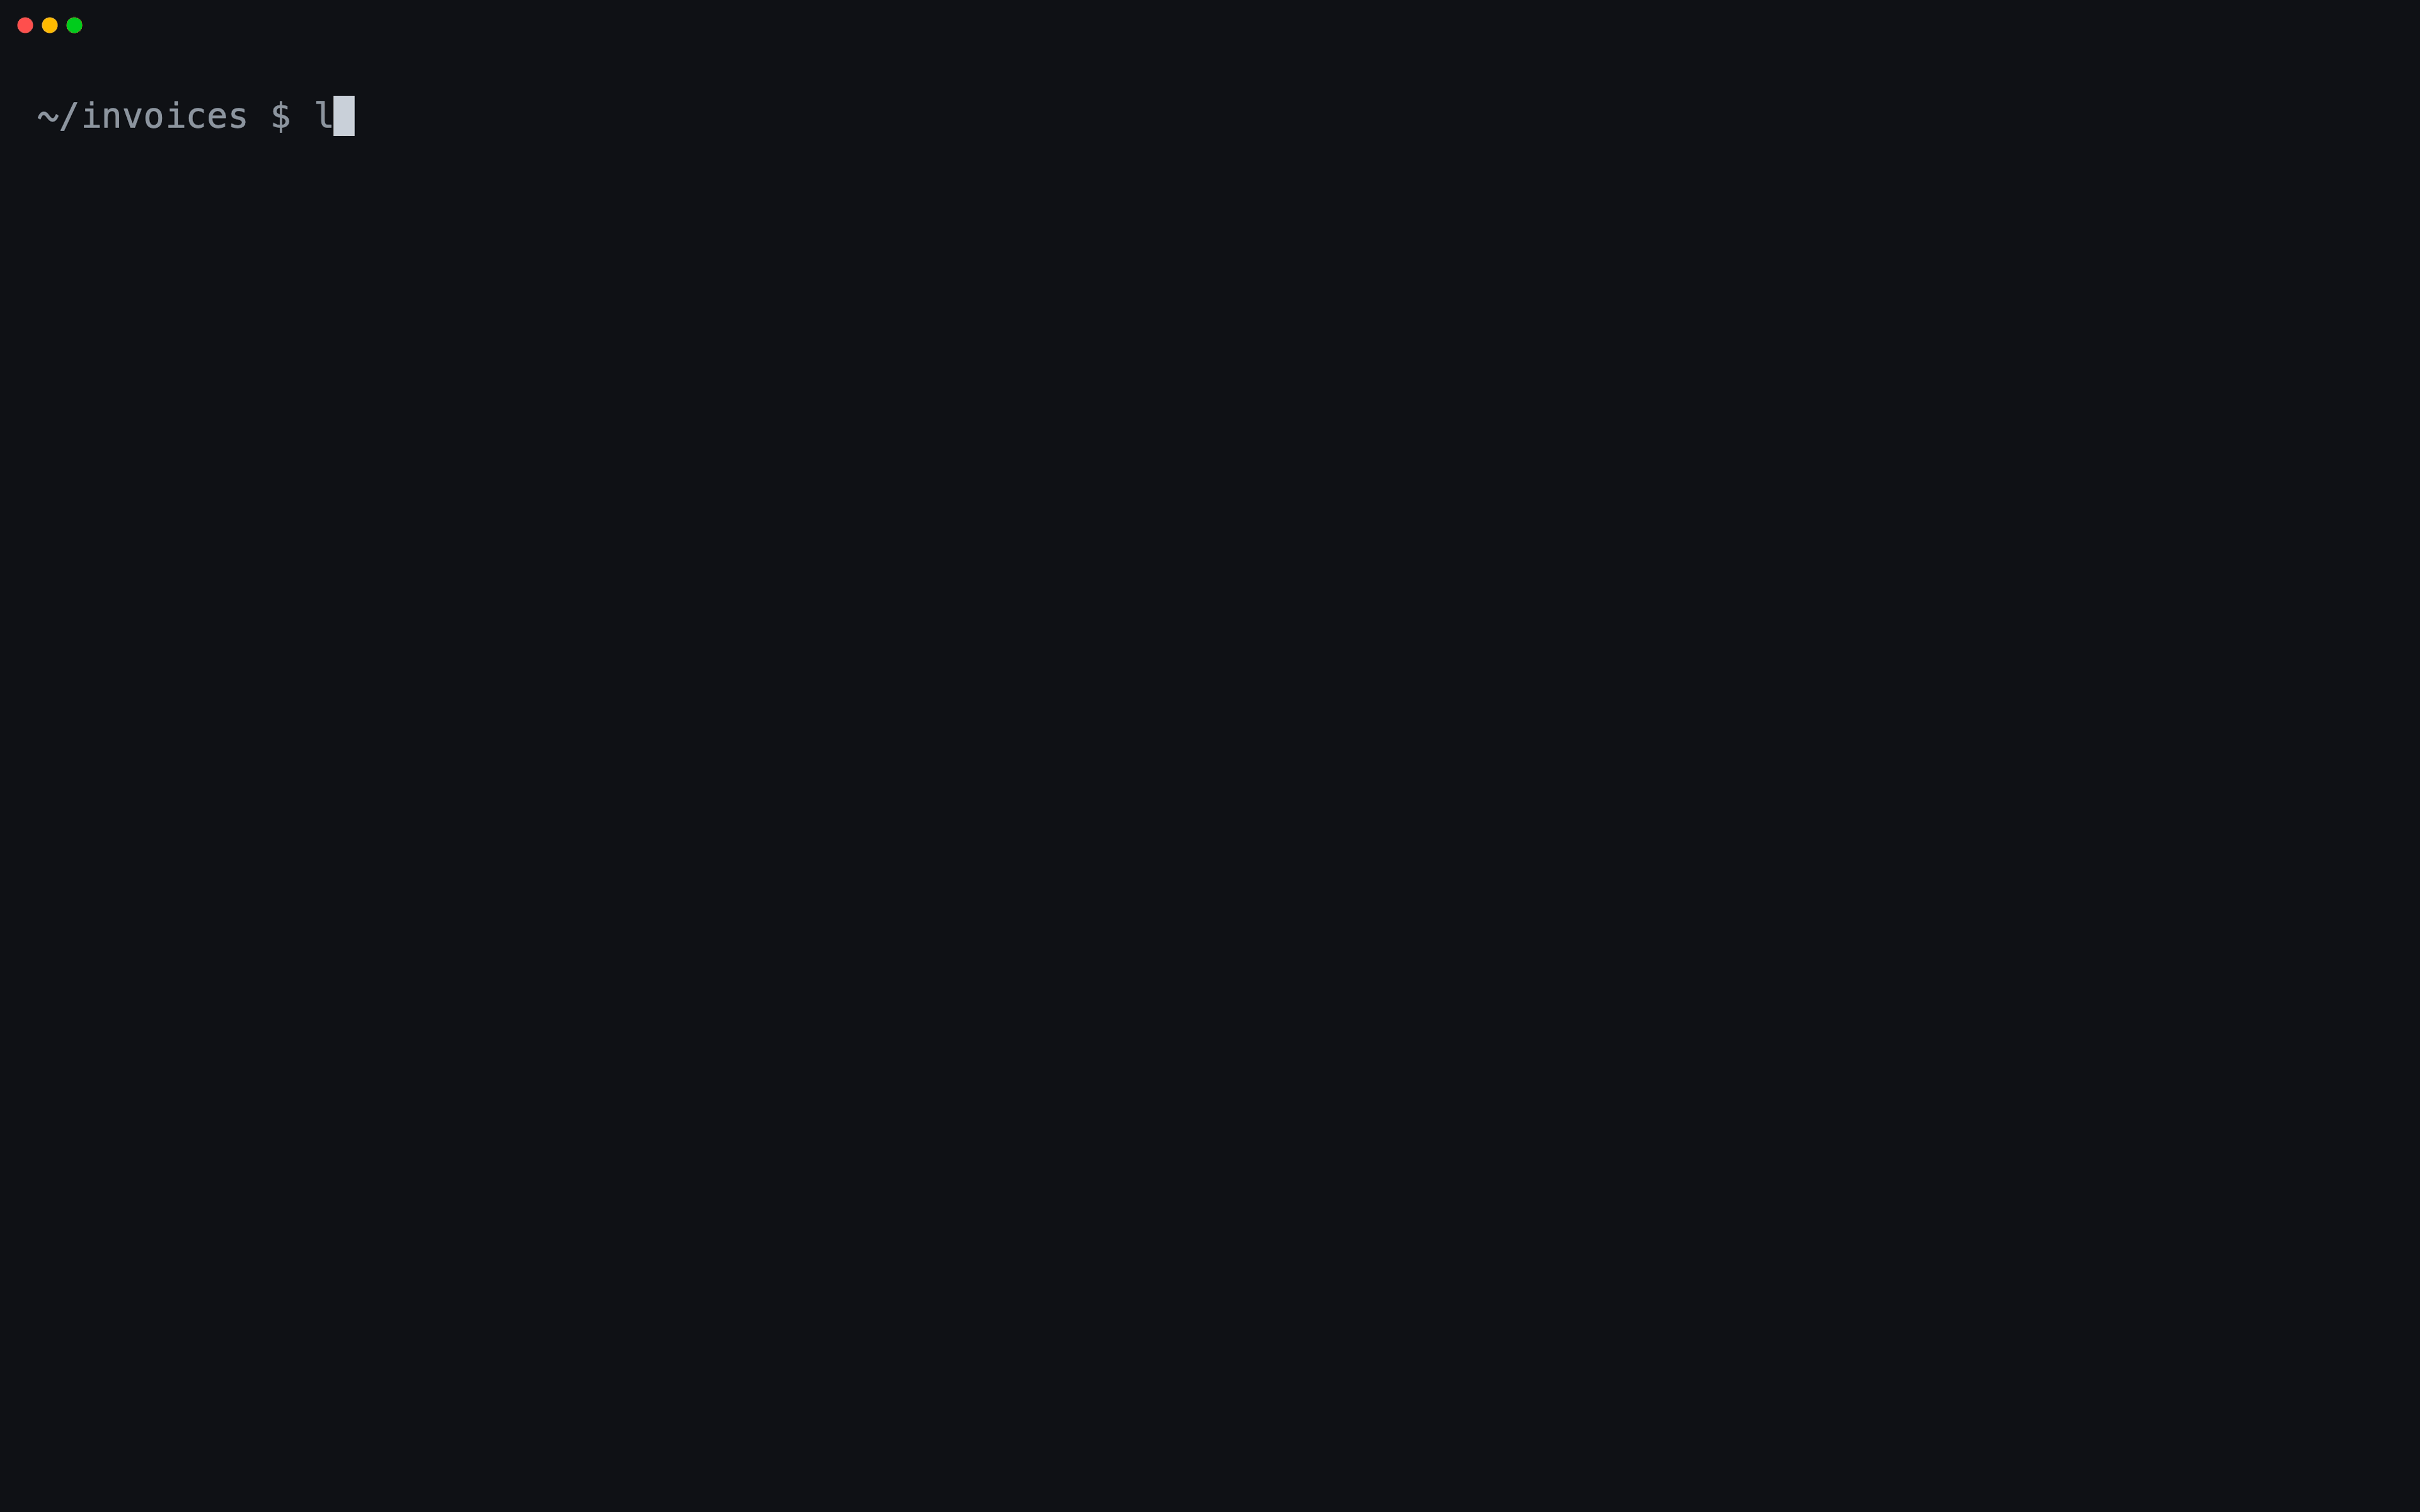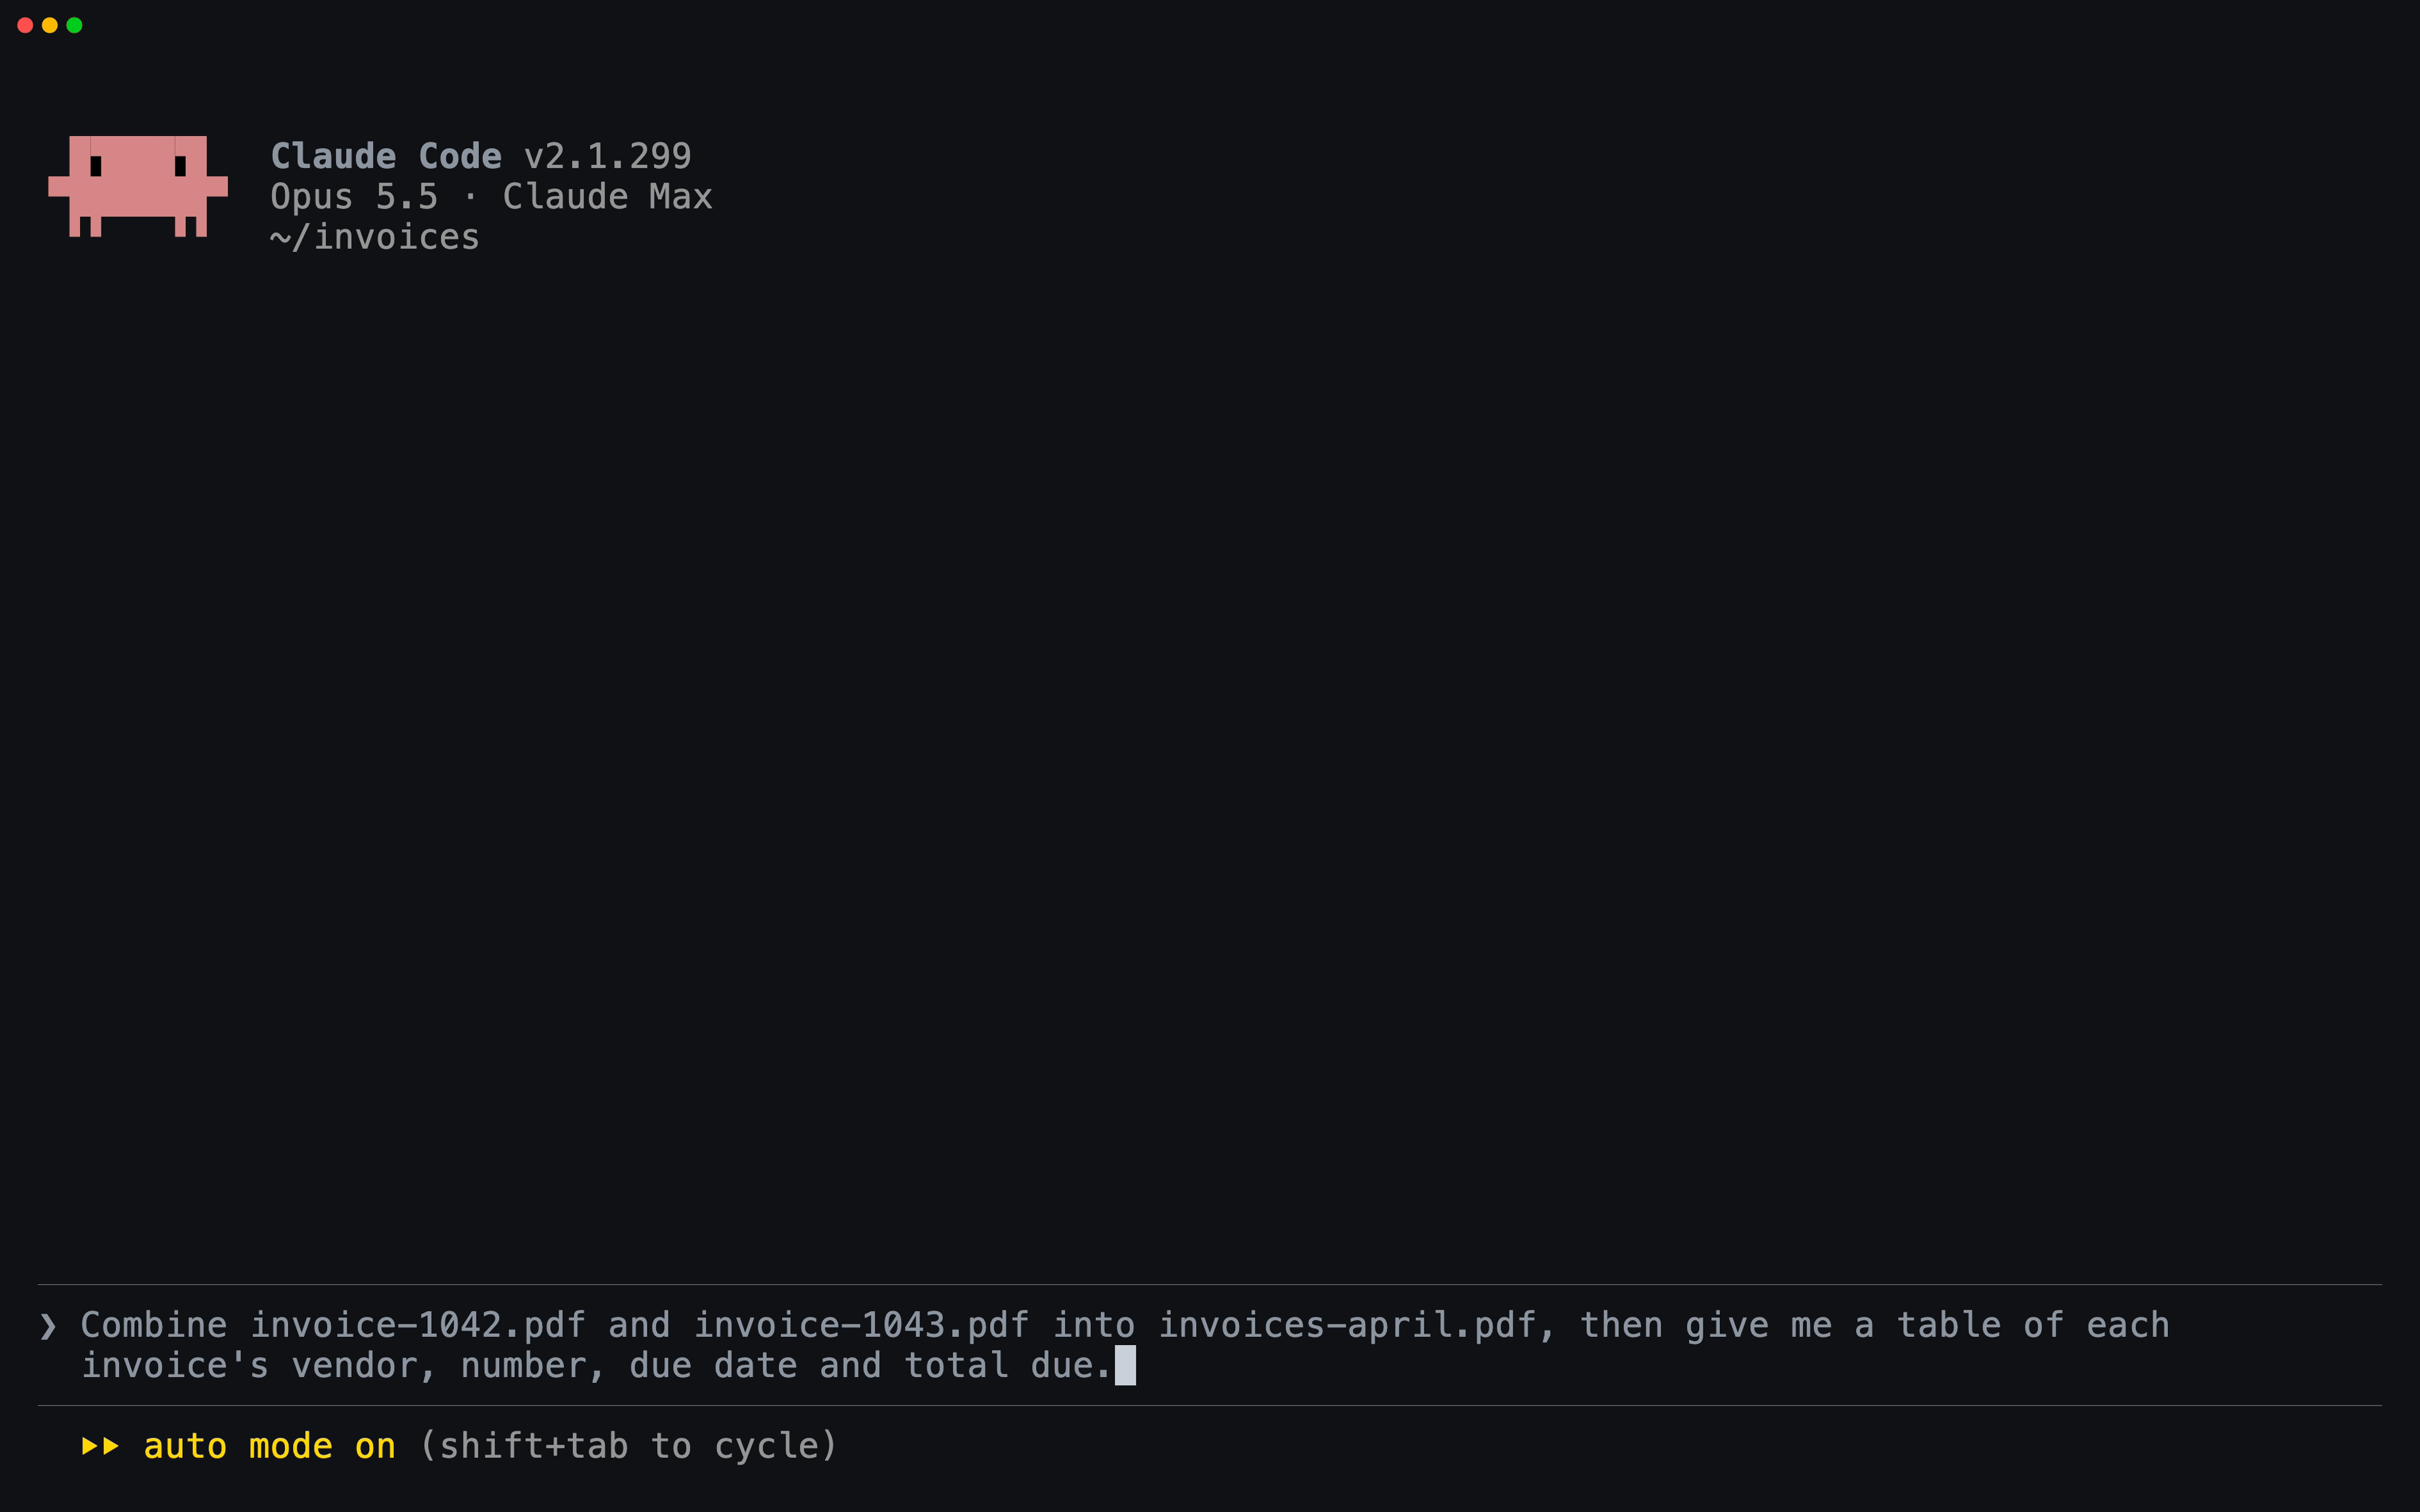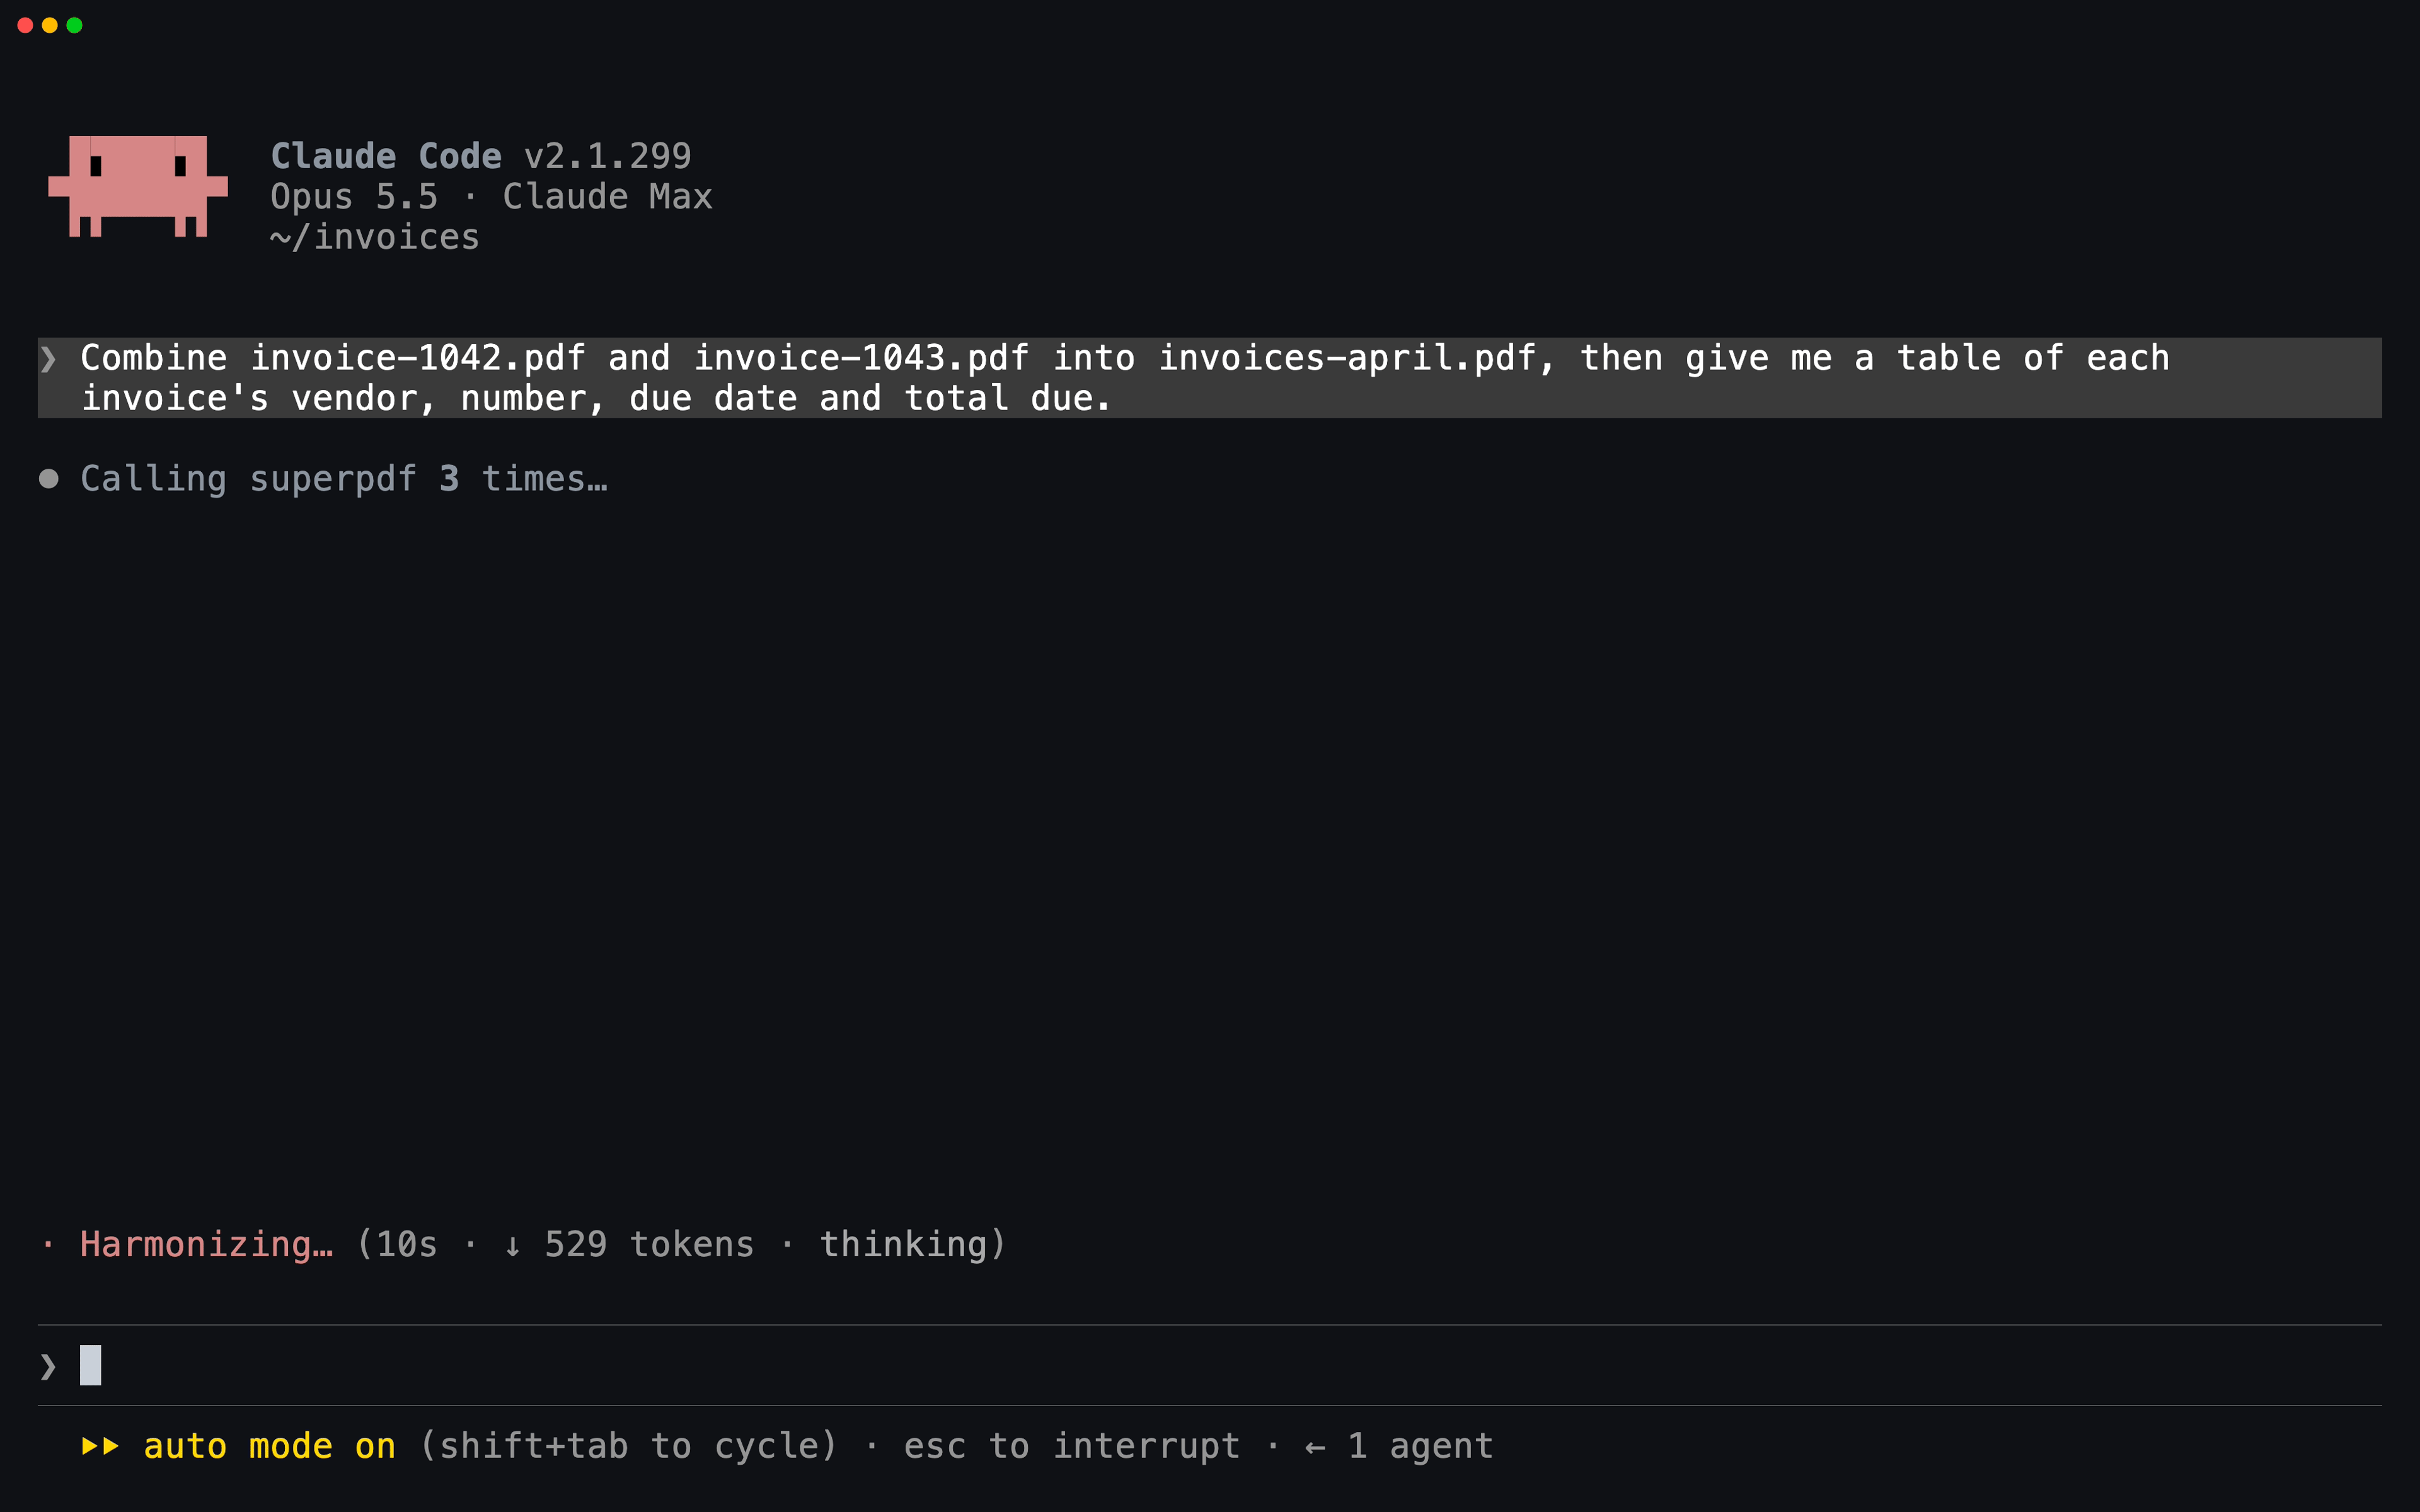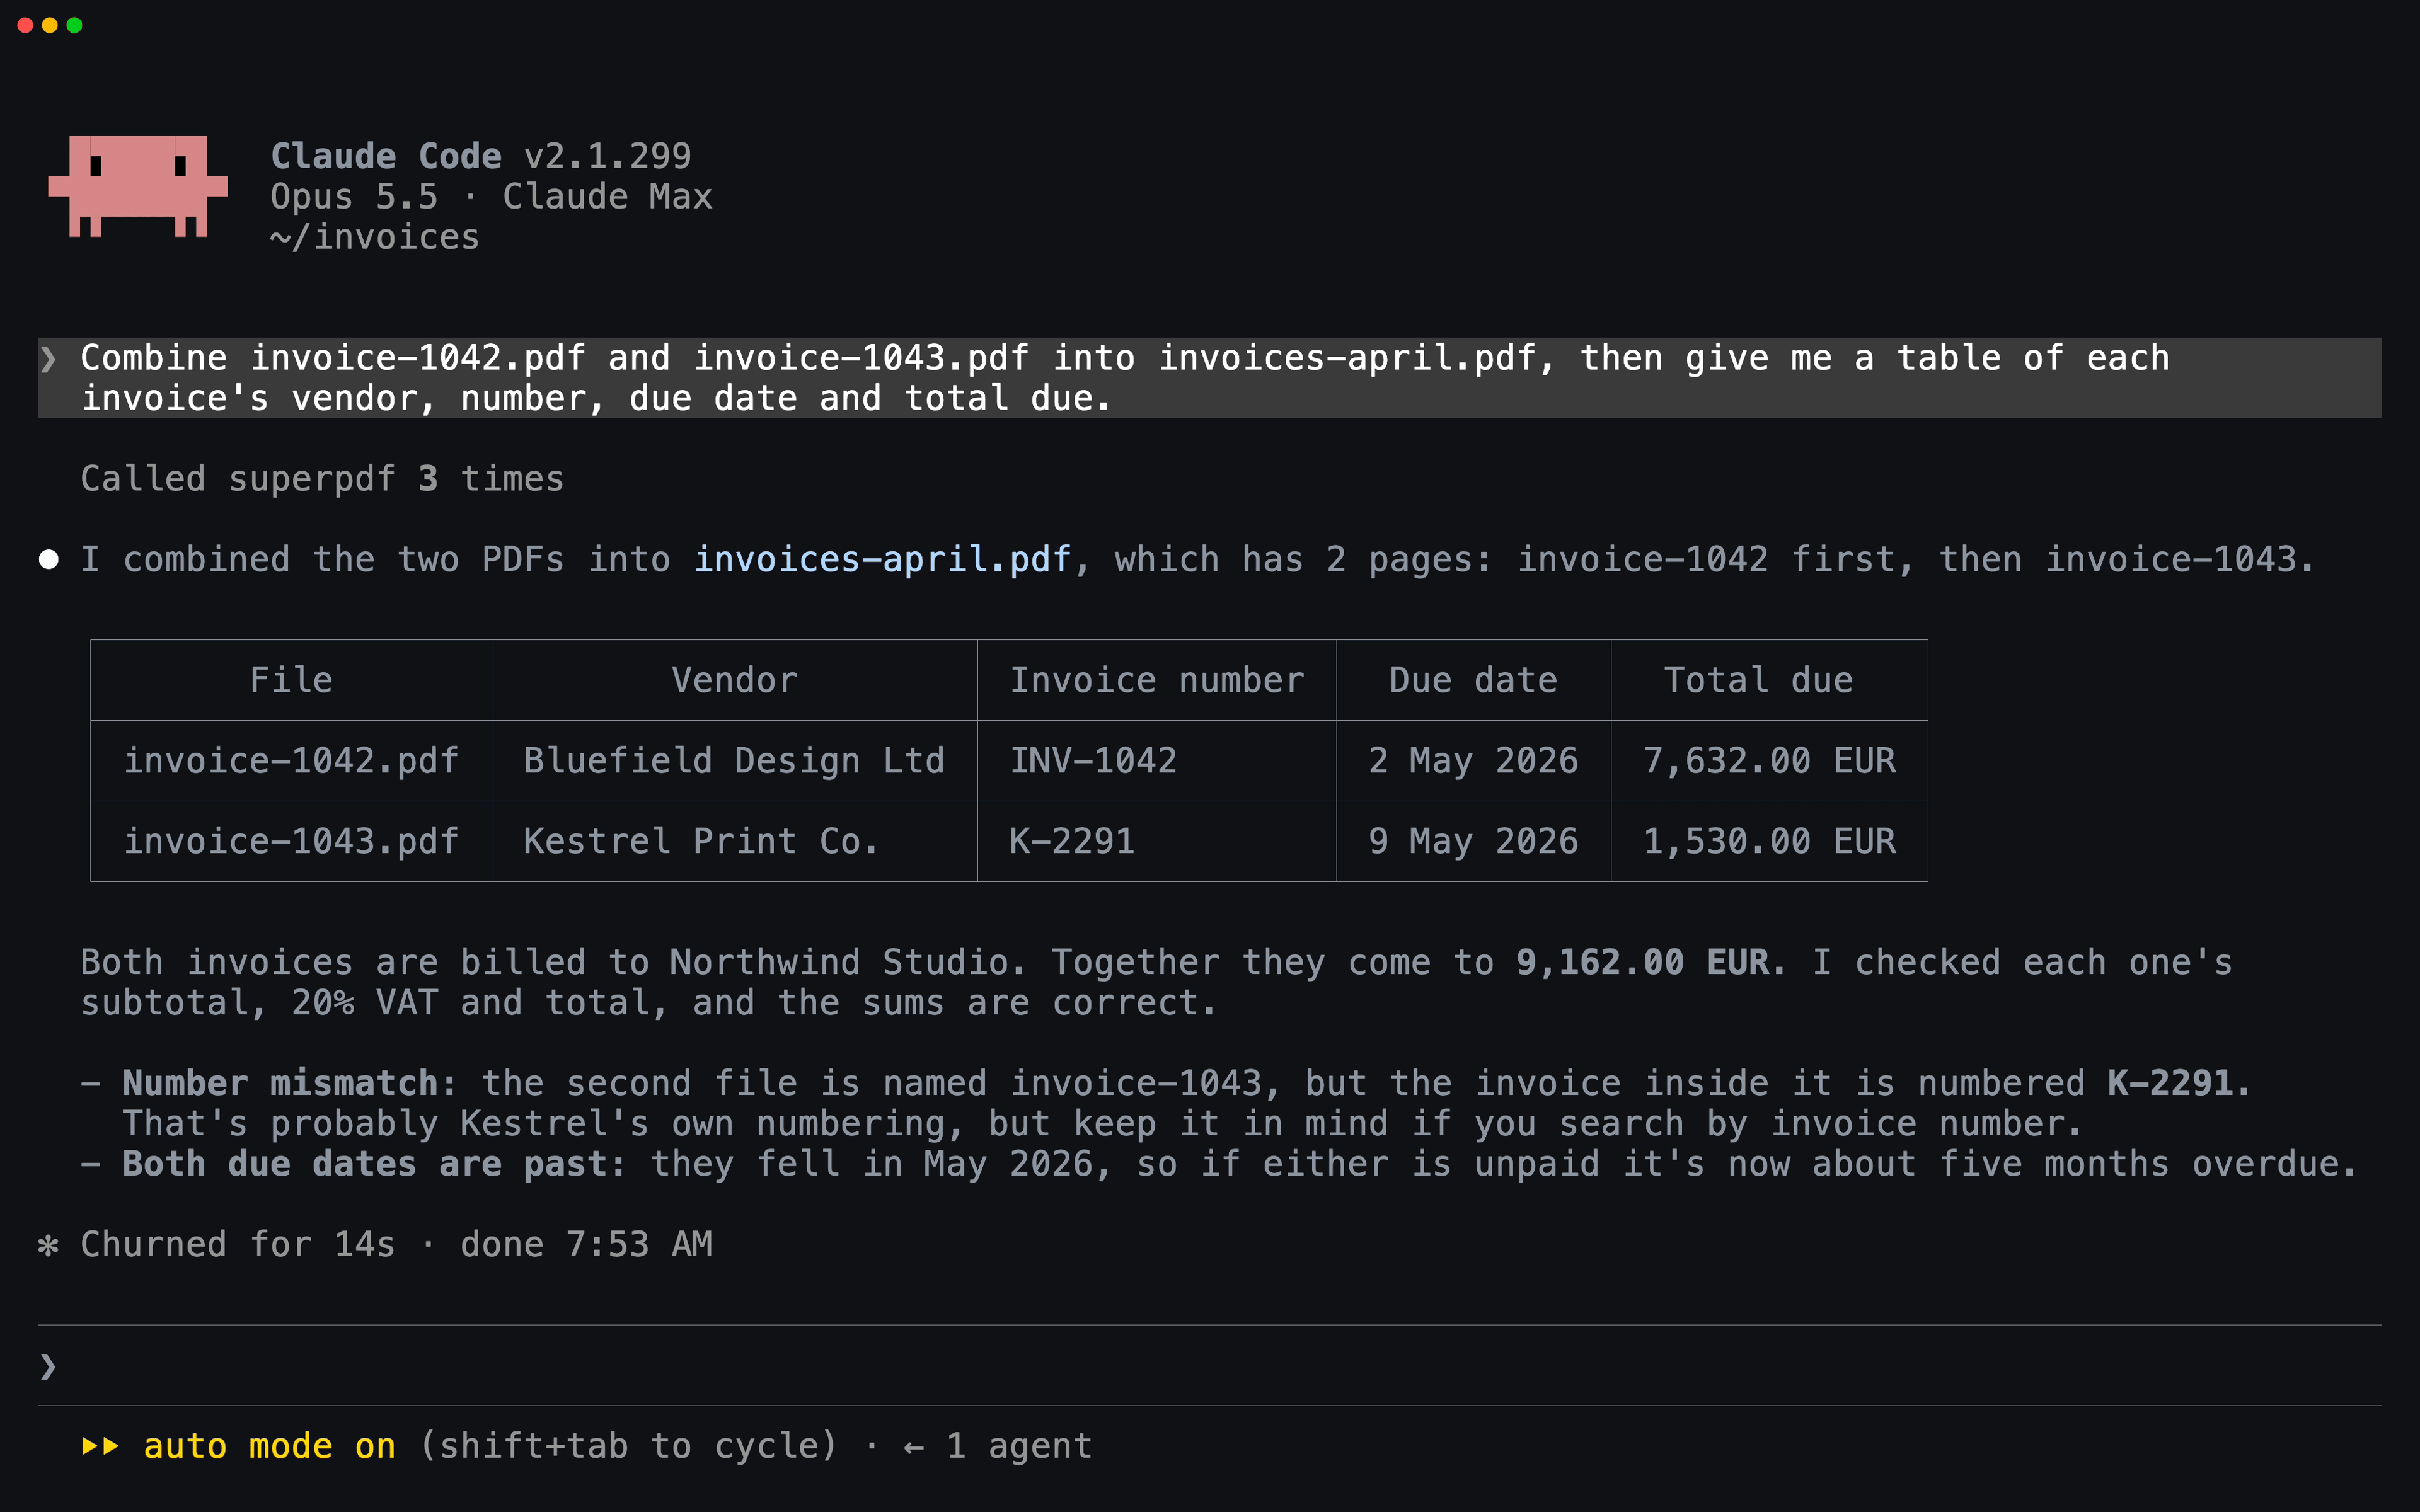
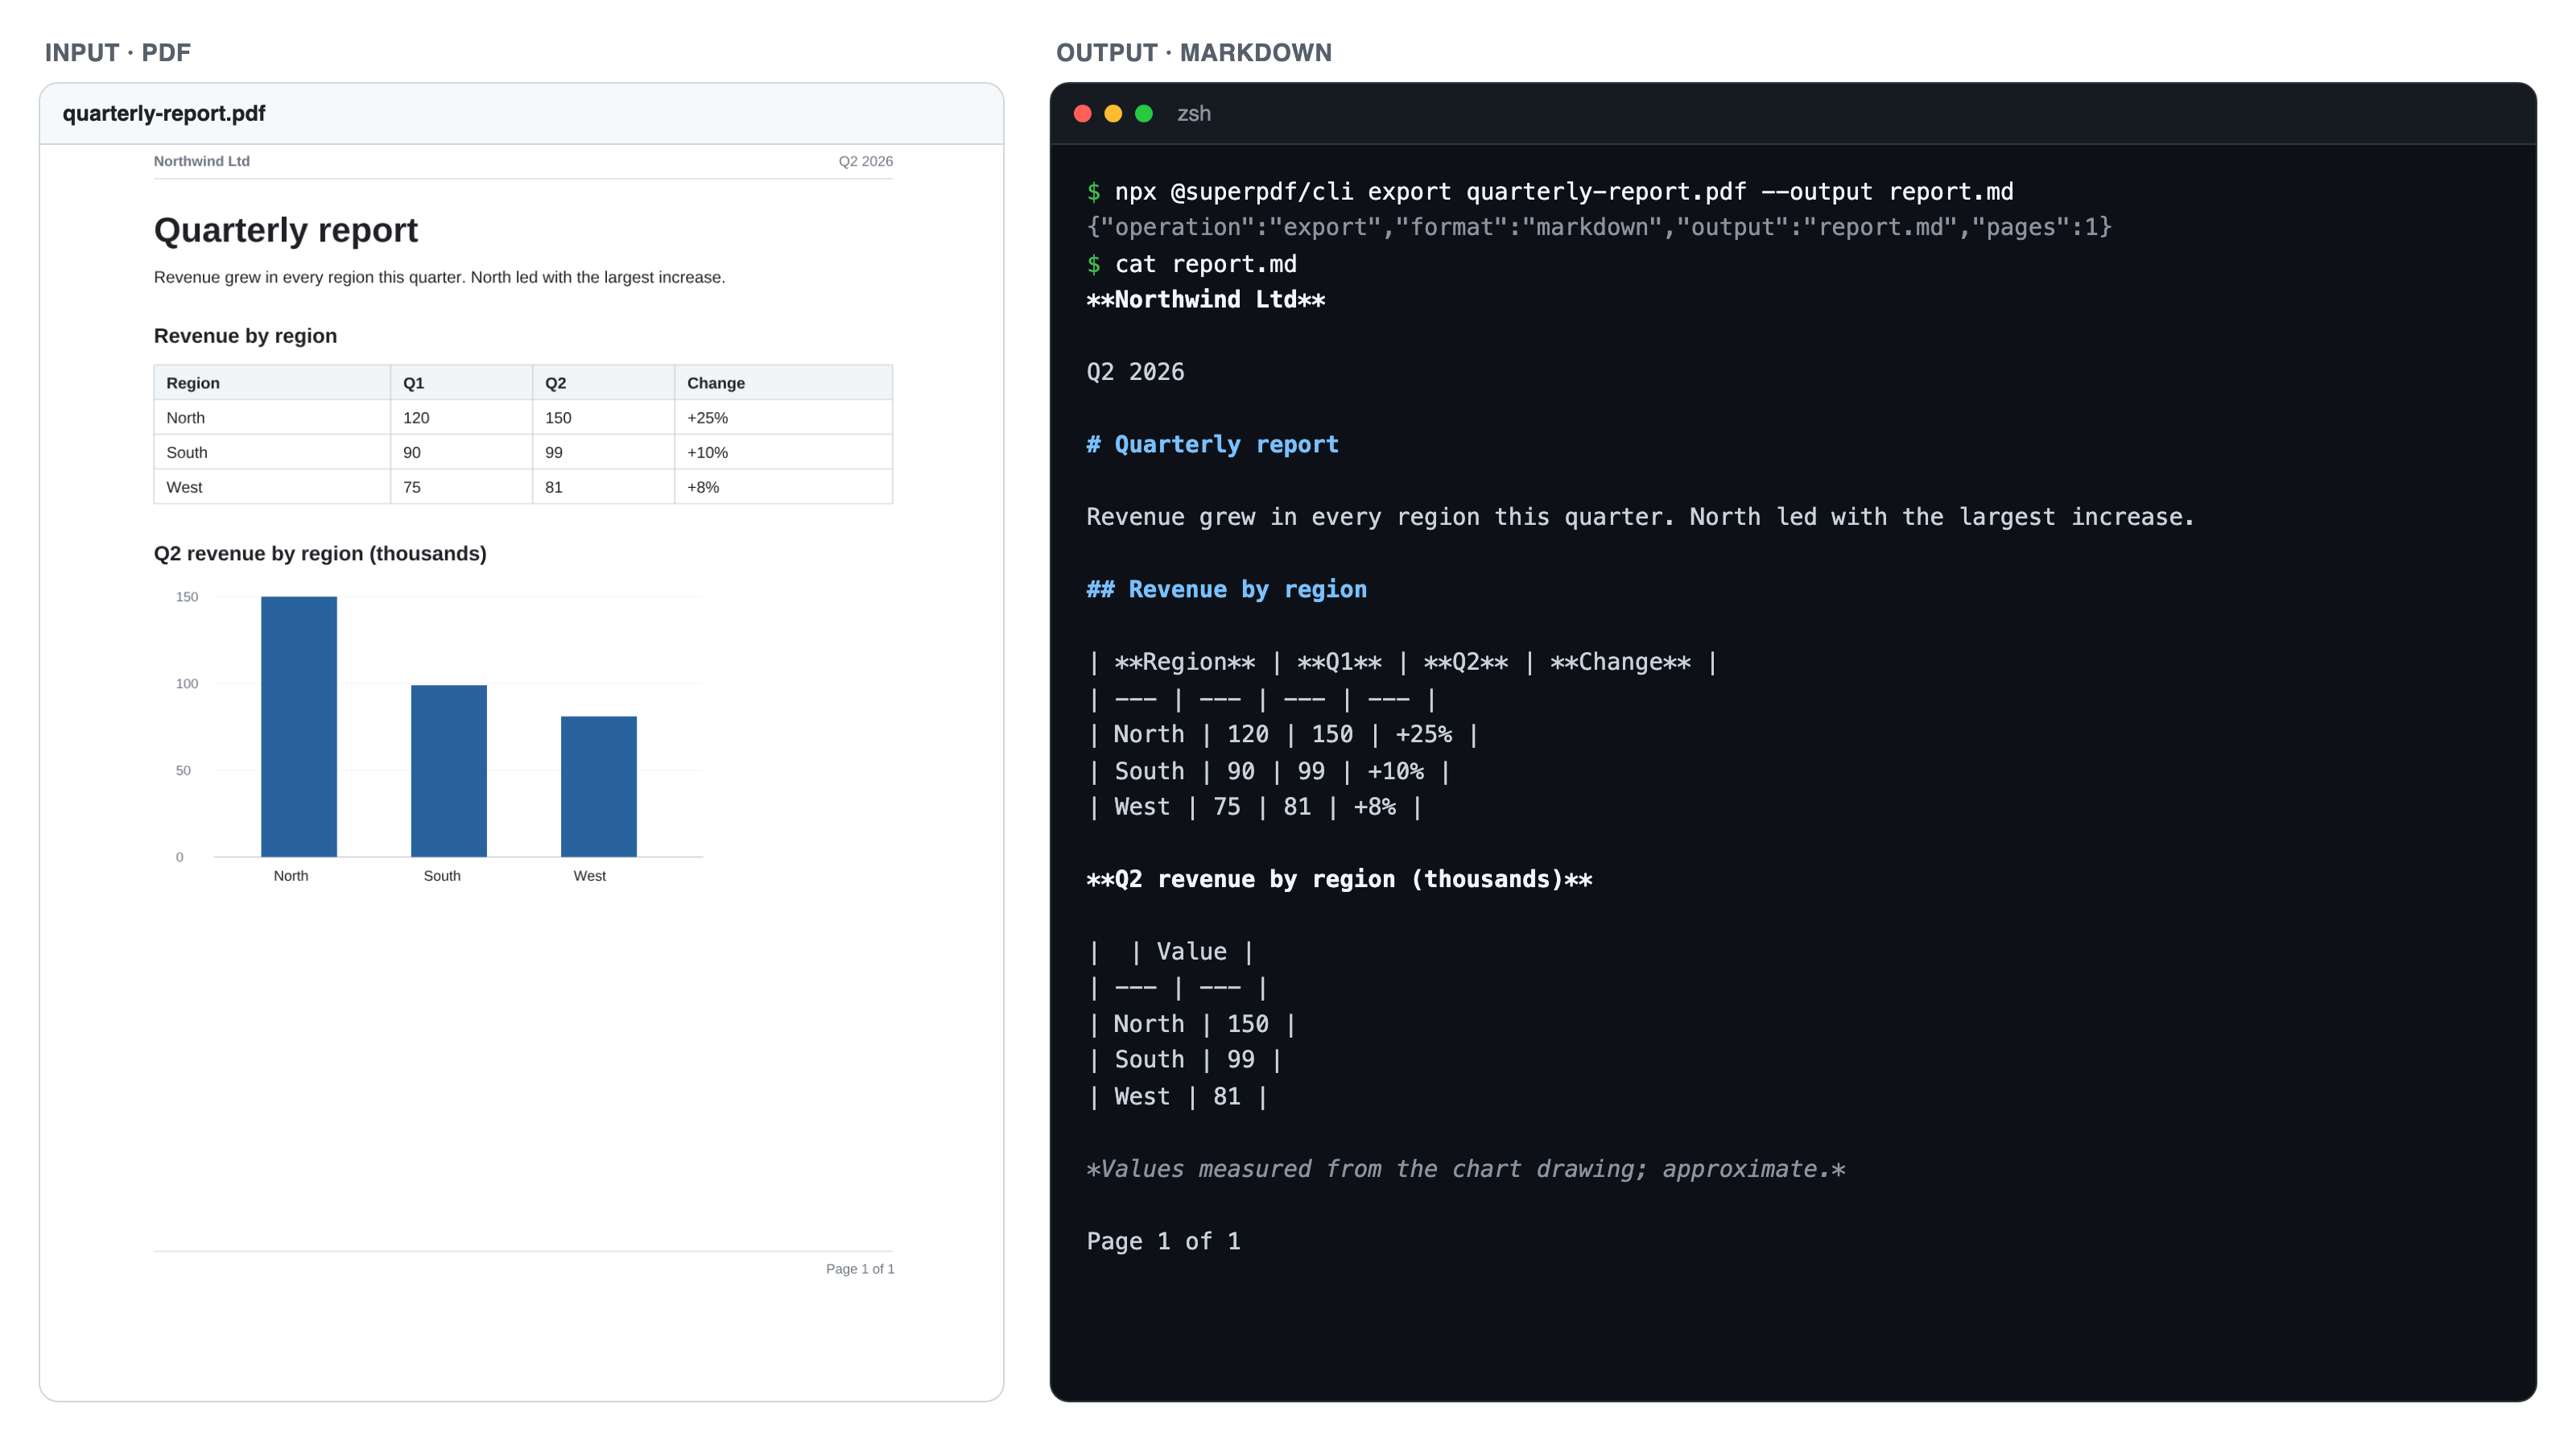
superPDF reads a PDF the way it was made: from the text, fonts and drawings inside it. It rebuilds the document as Markdown, HTML or JSON, with headings at the right level, tables with their rows and columns, and charts turned back into the numbers they were drawn from. Scanned pages are read with OCR in 15 languages.
It runs on your computer as a command, a Python package, an MCP server for AI assistants such as Claude Code, Cursor and Codex, or a local REST API for your own scripts. It only opens files in the folders you allow and never uploads them (through MCP, the text your assistant reads goes to its model, as with any file you show it). It is the same reader that powers superpdf.ai in the browser.
| Use it as | Install or run | Docs |
|---|---|---|
| Command line | npm install -g @superpdf/cli, or npx @superpdf/cli … without installing | CLI |
| Command line with Homebrew | brew install arjunprabhulal/superpdf/superpdf | Tap |
| MCP server for AI assistants | superpdf mcp --allow-dir ~/Documents/superPDF | MCP setup |
| Local REST API (OpenAPI 3.1) | superpdf serve --allow-dir ~/Documents/superPDF | API |
| JavaScript and TypeScript SDK | npm install @superpdf/cli, then import { toDocx } from '@superpdf/cli' | SDK |
| Python SDK | pip install superpdf or uv add superpdf | Python |
| Python, without installing | uvx superpdf … or pipx run superpdf … | Python |
| LangChain | pip install langchain-superpdf | Loader |
| LlamaIndex | pip install llama-index-readers-superpdf | Reader |
| LangGraph agents | the MCP server through langchain-mcp-adapters | Agents |
How it compares
On ParseBench, in our own run of its open-source test suite on all 2,078 documents, superPDF scores 65.0 overall (64.8 on documents it was never tuned on). It is not on the official leaderboard yet. The other scores are a selection from the public leaderboard (October 12, 2026).
| Parser | Overall | Tables | Charts | Content | Formatting | Grounding |
|---|---|---|---|---|---|---|
| LlamaParse Agentic Plus (paid service) | 90.2 | 93.4 | 94.2 | 92.3 | 87.1 | 84.1 |
| Claude Opus 5.5 (AI model) | 78.0 | 93.9 | 64.1 | 91.8 | 77.0 | 63.2 |
| superPDF (no language model, our run) | 65.0 | 68.4 | 52.2 | 80.5 | 62.3 | 61.5 |
| Azure Document Intelligence | 59.6 | 86.0 | 1.6 | 84.9 | 51.9 | 73.8 |
| Docling (docling-models) | 50.6 | 66.4 | 52.8 | 66.9 | 1.0 | 66.1 |
| Google Cloud Document AI | 50.4 | 55.1 | 1.4 | 83.7 | 50.5 | 61.3 |
| AWS Textract | 47.9 | 84.6 | 6.0 | 74.8 | 3.7 | 70.4 |
Compared with the Azure, Google and AWS services, superPDF scores much higher on charts and higher on formatting; Azure and Textract score higher on tables. LlamaParse and Claude Opus 5.5 score higher overall. Full table and method: superpdf.ai/performance.
Quick start
You need Node.js 22 or later.
Use it from the terminal
npx @superpdf/cli export report.pdf --output report.md
npx downloads the tool once and runs it. To install the superpdf command for regular use:
npm install -g @superpdf/cli
superpdf help
Or with Homebrew on macOS or Linux, which brings its own Node.js:
brew install arjunprabhulal/superpdf/superpdf
Use it from your AI assistant (MCP)
Create the folder the assistant may use, then add the server. For Claude Code:
mkdir -p ~/Documents/superPDF
claude mcp add --scope user superpdf -- npx -y @superpdf/cli mcp --allow-dir ~/Documents/superPDF
For Cursor, Claude Desktop and other assistants that read an MCP settings file:
{
  "mcpServers": {
    "superpdf": {
      "command": "npx",
      "args": ["-y", "@superpdf/cli", "mcp", "--allow-dir", "/Users/you/Documents/superPDF"]
    }
  }
}
With the command installed (npm install -g @superpdf/cli), use superpdf mcp --allow-dir … in place of
npx -y @superpdf/cli mcp --allow-dir …. Then ask, for example: "Read invoice.pdf in my superPDF folder and give me
the line items as a table." The assistant can only use the folders you pass with --allow-dir. Setup for each
assistant: superpdf.ai/docs/mcp-api/mcp-tool-access.
Use it from Python
pip install superpdf # or run without installing: uvx superpdf export report.pdf --output report.md
import superpdf

markdown = superpdf.export("report.pdf")
pages = superpdf.export_pages("report.pdf")        # Markdown per page

superpdf.merge(["a.pdf", "b.pdf"], "combined.pdf")  # every tool is a typed function
superpdf.extract_tables("report.pdf", "tables.xlsx")
superpdf.to_docx("report.pdf", "report.docx")

from superpdf.langchain import SuperPDFLoader       # pip install "superpdf[langchain]"
docs = SuperPDFLoader("report.pdf").load()
Node.js comes with the package. All 30 tools, a LlamaIndex reader and the full reference are in the Python docs and python/README.md.
Use it from JavaScript or TypeScript
npm install @superpdf/cli
import { exportPages, extractTables, toDocx, SuperPDFError } from '@superpdf/cli';

const pages = await exportPages('report.pdf');          // [{ page: 1, markdown: '# Quarterly report…' }]
const word = await toDocx({ input: 'report.pdf', output: 'report.docx' });
await extractTables({ input: 'report.pdf', format: 'csv', output: 'tables.csv' });
Every tool is an async function (merge, split, fillForm, compare, runBatch and the rest; tools() lists
them) that takes the tool's JSON input and returns its typed result. It runs in your Node.js process (22 or later):
no server, no subprocess. TypeScript types come with the package, generated from the same schemas as the MCP server
and the API. Errors are SuperPDFError with a code (validation, conflict, not_found, operation_failed).
Each call may only use the folders of the paths you give it, or the ones you pass as { allowDirs }.
Use it from your own code (REST API)
superpdf serve --allow-dir ~/Documents/superPDF
This starts a private API on 127.0.0.1 that only this computer can reach. It prints a token when it starts (or set
SUPERPDF_API_TOKEN, at least 32 characters); every request under /v1/ needs it. The OpenAPI 3.1 document is served at /openapi.json (also
openapi.json here, generated from the tool schemas). Guide and reference:
superpdf.ai/docs/api.
What it reads
| Part of the PDF | How superPDF reads it |
|---|---|
| Tables | Ruled tables from their lines (shading inside them splits rows), borderless tables from aligned text; --tables html keeps merged header cells |
| Charts | Bar, line, dot, area and pie charts drawn as shapes, turned into tables of values; values measured from the drawing, not printed on it, are marked approximate |
| Structure | Headings and their levels, paragraphs, lists, bold and italic text, page headers and footers |
| Reading order | Multi-column pages split at their column gaps, so the text reads in order |
| Scans | Pages without a text layer are read with Tesseract OCR in English and 14 other languages; the language data is bundled, so nothing is downloaded |
| Big files | No page limit; files up to 2 GB |
Commands
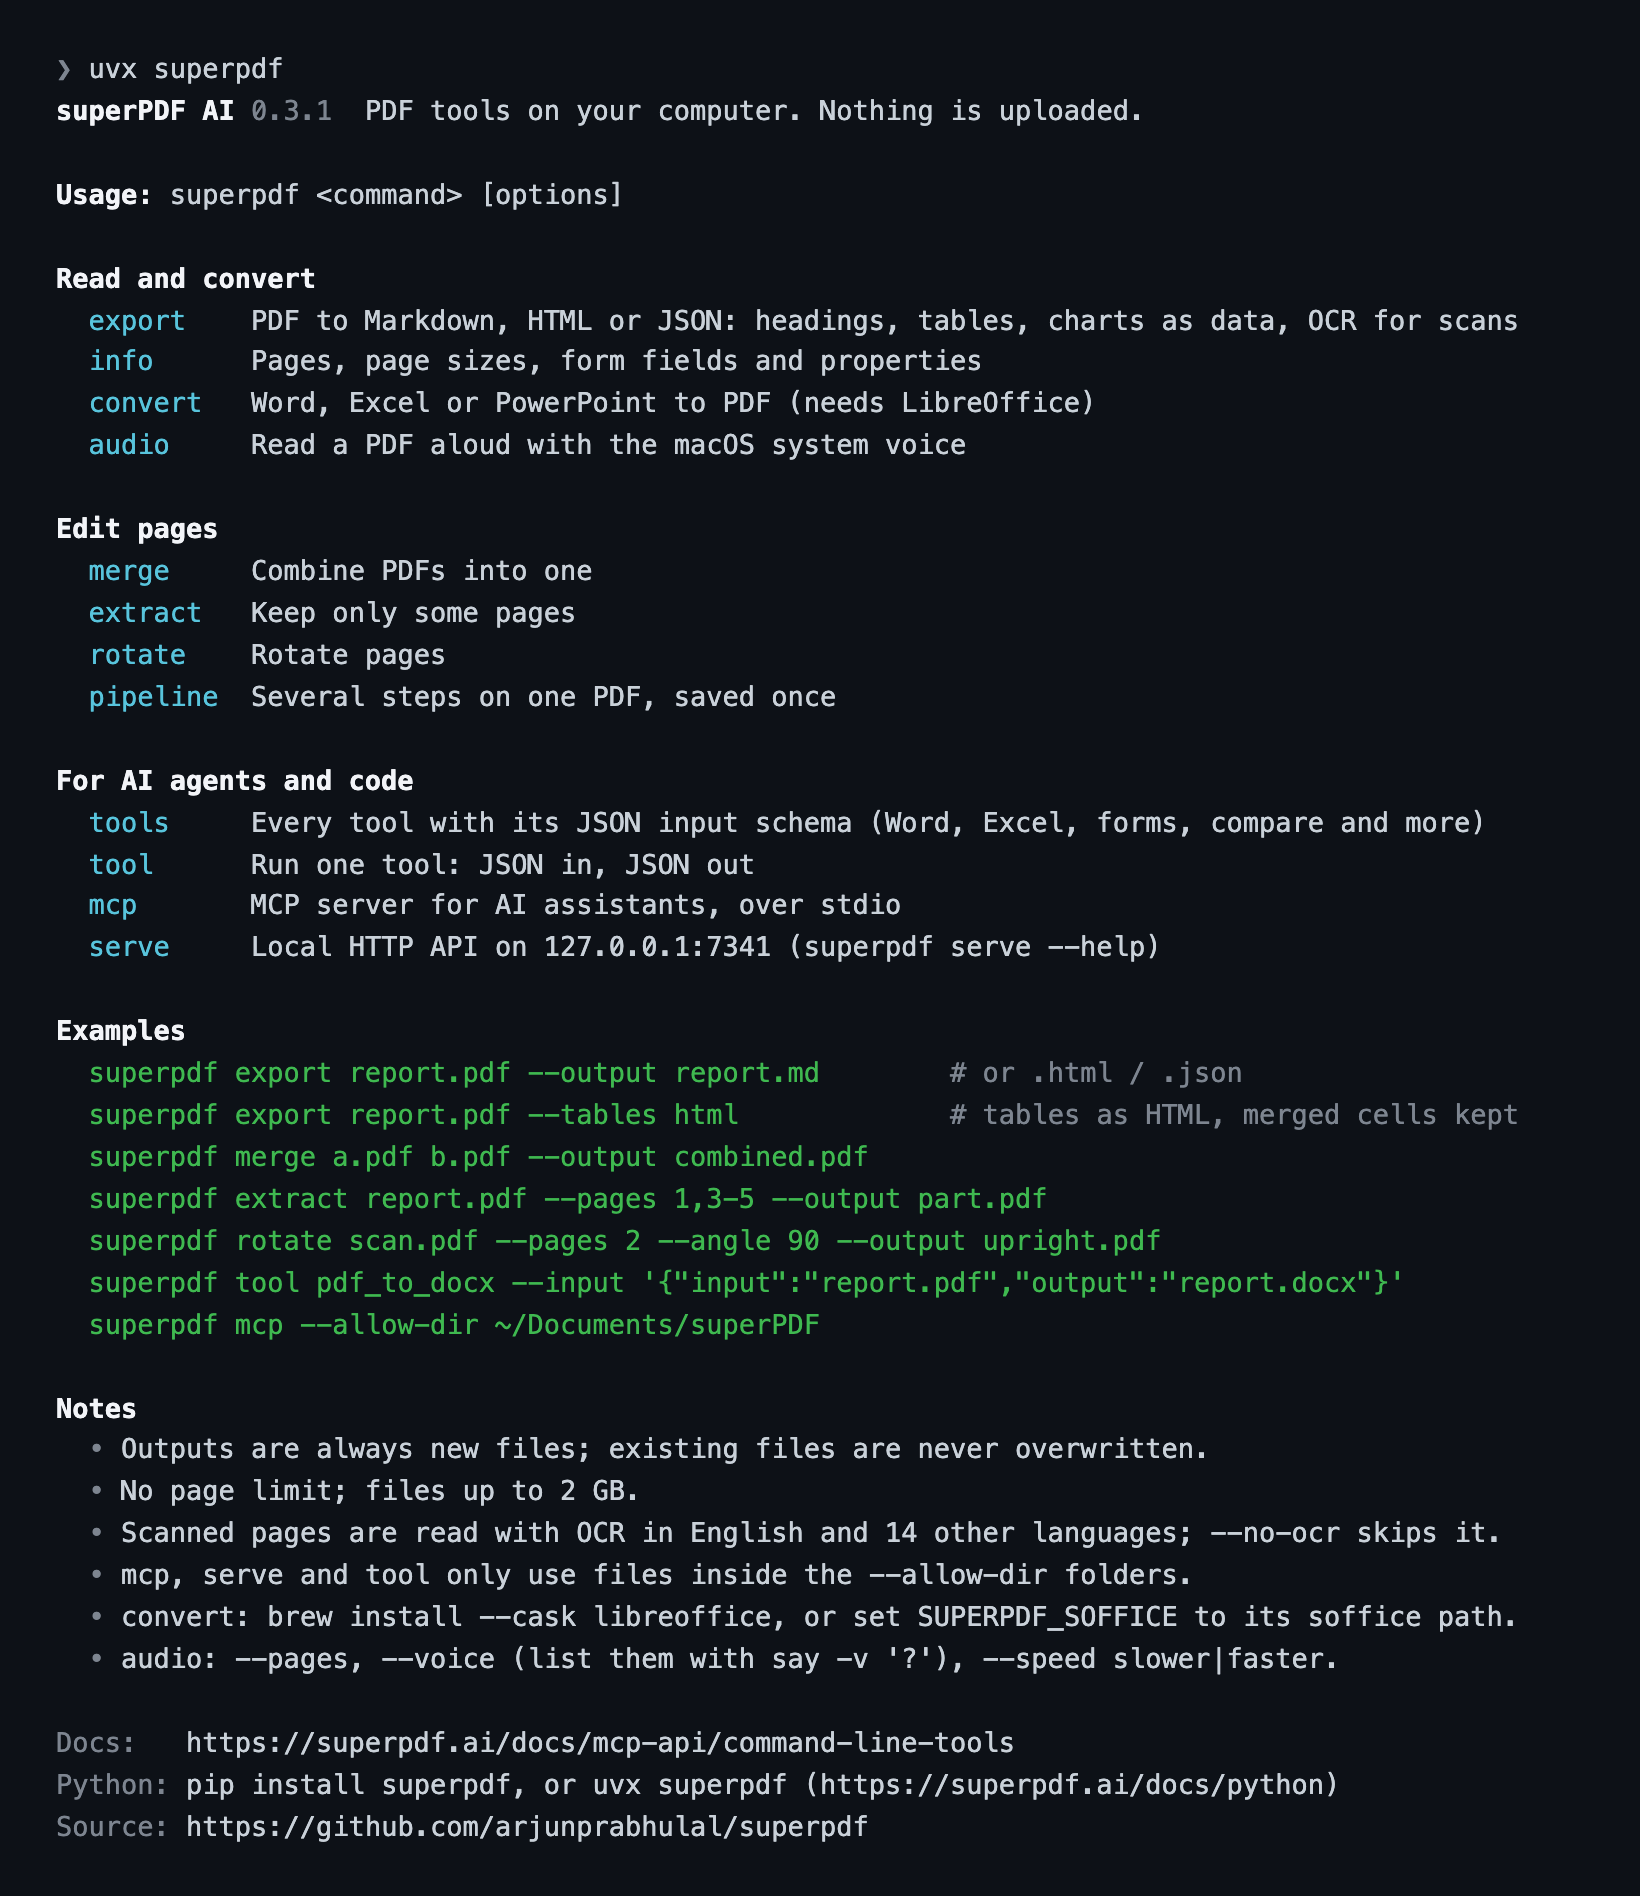
superpdf info document.pdf                                    # pages, sizes, form fields, properties
superpdf merge a.pdf b.pdf --output combined.pdf
superpdf extract document.pdf --pages 1,3-5 --output selected.pdf
superpdf rotate document.pdf --pages 2 --angle 90 --output rotated.pdf
superpdf export document.pdf --output document.md             # or .html / .json (--format)
superpdf export document.pdf --tables html --output doc.md    # tables as HTML, keeping merged header cells
superpdf convert report.docx --output report.pdf              # Word, Excel, PowerPoint; needs LibreOffice
superpdf pipeline document.pdf --steps steps.json --output result.pdf
superpdf audio document.pdf --output document.m4a             # read aloud with the macOS system voice
superpdf tools                                                # all 30 tools with their JSON input schemas
superpdf tool pdf_protect --input '{"input":"a.pdf","password":"…","output":"locked.pdf"}'   # any tool, JSON in and out
Results are always written to a new file; existing files are never overwritten. superpdf help shows every command.
Try info and export on examples/quarterly-report.pdf, a one-page report.
MCP tools
| Tool | What it does |
|---|---|
pdf_list_files | List the PDFs in an allowed folder |
pdf_info | Page count, page sizes, form fields and properties |
pdf_read_text | The embedded text, page by page |
pdf_extract_structure | Markdown, HTML or JSON with headings, tables, charts and lists |
pdf_merge, pdf_split, pdf_extract_pages, pdf_remove_pages | Combine and separate pages into new PDFs |
pdf_extract_tables | Tables and vector charts as Excel, CSV, JSON or Markdown |
pdf_outline, pdf_compare | The outline with each section's pages; what changed between two versions, page by page |
pdf_to_docx, pdf_to_pptx, pdf_to_epub | Editable Word, PowerPoint (text as text boxes) and EPUB 3 |
pdf_from_images, pdf_from_markdown | JPG and PNG images, or a Markdown file, to PDF |
pdf_fill_form, pdf_flatten | Fill form fields by name; make fields part of the page |
pdf_add_text, pdf_resize_pages | Typed signatures and notes; crop margins or scale pages |
pdf_rotate_pages, pdf_add_page_labels, pdf_add_watermark | Rotate, number (header or footer) and stamp pages |
pdf_protect, pdf_unlock, pdf_remove_metadata, pdf_repair | AES-256 passwords, clean properties, fix damaged files |
pdf_from_office | Word, Excel and PowerPoint to PDF (needs LibreOffice) |
pdf_run_pipeline, pdf_run_batch | Up to 10 steps on one PDF, or the same steps on up to 50 PDFs |
What makes it different
Most PDF-to-text tools take the text layer and sort it by position, or run an AI model on a picture of the page. superPDF works from the PDF's own drawing instructions, which keeps exact text and positions and recovers things both approaches tend to lose:
- Charts become data. Bars, lines, dots, areas and pie slices are drawn as shapes;
pdf-charts.jsmeasures bars, lines, dots and areas against the axis labels (or, without an axis, against the values printed on them), reads pie slices from their angles, and matches series to their legend colours. Charts saved as pictures fall back to reading the bars' pixels. - Lost letters are recovered. When a font has no proper Unicode table, PDF.js reads its letters as blanks or leaves them out.
pdf-text-fixes.jsmatches each glyph's outline against letters it has already identified, and checks TrueType fonts against the standard Mac glyph order, then puts the letters back. - Bold is measured, not guessed. Font names are often hidden (
F1,g_d0_f2), sopdf-structure.jsmeasures the glyphs' stroke thickness, compares the widths of two cuts of one font, and detects text drawn twice or outlined to look bold. On scans it measures the ink thickness of each word. - Spacing and hidden text are fixed. False spaces that PDF.js inserts in letter-spaced words and around Chinese and Japanese characters are removed by measuring the glyphs the page draws, text drawn outside a rectangular clipping area is left out, and Arabic lam-alef ligatures that come out with their letters swapped are corrected.
- OCR only where it's needed. Whole scanned pages, pages whose font encoding is garbled, and pictures that contain text (checked first for letter-like shapes, so photos don't produce noise). The language comes from the PDF's language tag or the text itself, and a poor reading is retried with Sauvola thresholding.
- Tables three ways. Ruled lines, lines found in the pixels of scanned pages, and borderless tables from aligned columns of text (on pages with a text layer).
How it works
- Read. PDF.js gives the text with its fonts and positions, and the drawing operations (lines, rectangles, curves).
- Recognize. Scanned or garbled pages, and pictures that contain text, go through Tesseract OCR.
- Repair. Letters drawn without a Unicode mapping are recovered from their outlines, and spacing is fixed.
- Rebuild. Rules group the text into lines and blocks, find table grids and borderless columns, read charts from their shapes and axis labels, size headings from the fonts and order columns for reading.
- Write. Markdown, HTML or JSON; the JSON keeps each block's page and position.
The reader lives in lib/: pdf-structure.js (pages to blocks), pdf-layout.js (lines, tables, reading
order), pdf-charts.js (charts) and pdf-text-fixes.js (text repairs). Ideas adapted from pdfplumber, Camelot,
tabula-java and others are credited in NOTICE.
Privacy and security
- Everything runs on your computer. The only network requests superPDF makes are the job callbacks (webhooks) you configure for the API; the OCR language data is in the package.
- The MCP server and the API read and write only inside the
--allow-dirfolders; paths are resolved through symlinks, so they can't escape. - The API listens on
127.0.0.1only and needs its bearer token on every request under/v1/. - Outputs are written to new files; existing files are never overwritten.
Found a security issue? See SECURITY.md.
Contributing
Issues and pull requests are welcome. For a reading problem, attach the PDF (or one page of it) and the output you expected. See CONTRIBUTING.md.
License
Apache-2.0. Credits for adapted ideas and bundled data are in NOTICE. "superPDF" and its logo are the project's marks and are not covered by the licence.
Installation
Source-derived launch command. Check the maintainer’s required arguments and credentials before running:
npx -y @superpdf/cliSet up in your AI client
Merge this template into ~/Library/Application Support/Claude/claude_desktop_config.json. Keep existing servers. Add any arguments, credentials, and permissions required by the maintainer; this template has not been install-tested.
{
  "mcpServers": {
    "io-github-arjunprabhulal-superpdf": {
      "command": "npx",
      "args": [
        "-y",
        "@superpdf/cli"
      ]
    }
  }
}
Restart Claude Desktop completely for changes to take effect. Confirm the server appears connected in the client’s tool list, then try a read-only example from its documentation.
Claude Desktop setup referencePackage
Compatible MCP Clients
superPDF AI works with any MCP-compatible client. Copy the config snippet from the Configuration section above and add it to the file shown for your client, then restart the application.
- Claude Desktop
~/Library/Application Support/Claude/claude_desktop_config.jsonRestart Claude Desktop completely for changes to take effect. - Cursor
~/.cursor/mcp.jsonRestart Cursor for changes to take effect. - VS Code
.vscode/mcp.jsonReload VS Code window for changes to take effect. - Windsurf
~/.codeium/windsurf/mcp_config.jsonRestart Windsurf for changes to take effect. - Claude Code
.mcp.jsonSave at the project root, then start Claude Code in that project and review the MCP server approval prompt. Keep real credentials out of shared files.